Transformer: A Top-Down Explanation

Nicolae Vartolomei · 2026/10

Work in progress

Alternative titles: Applying the Feynman Technique to Understanding the Transformer Architecture, or The Life of a Token Inside a Transformer, or The Transformer for the Impatient.

Intro

In 2017, researchers at Google publish the Attention Is All You Need1 paper, in which they introduce the Transformer architecture. The world runs with it.

Soon after, researchers at OpenAI develop a belief that this architecture scales better than anything they’ve seen. In 2020, they publish the Scaling Laws for Neural Language Models2 paper and keep feeding data and compute to a variant of the Transformer, which they then teach to follow instructions3. In November 2022, ChatGPT is born.

The field has moved fast since, but today’s large language models (LLMs) are still Transformers. Understanding the original gives you a point of reference for everything that came after. At least that’s my bet.

So let’s travel back to 2017 and figure out how the sausage token is made.

My focus here is on the arithmetic, not intelligence.

High-level Overview

Transformer architecture diagram

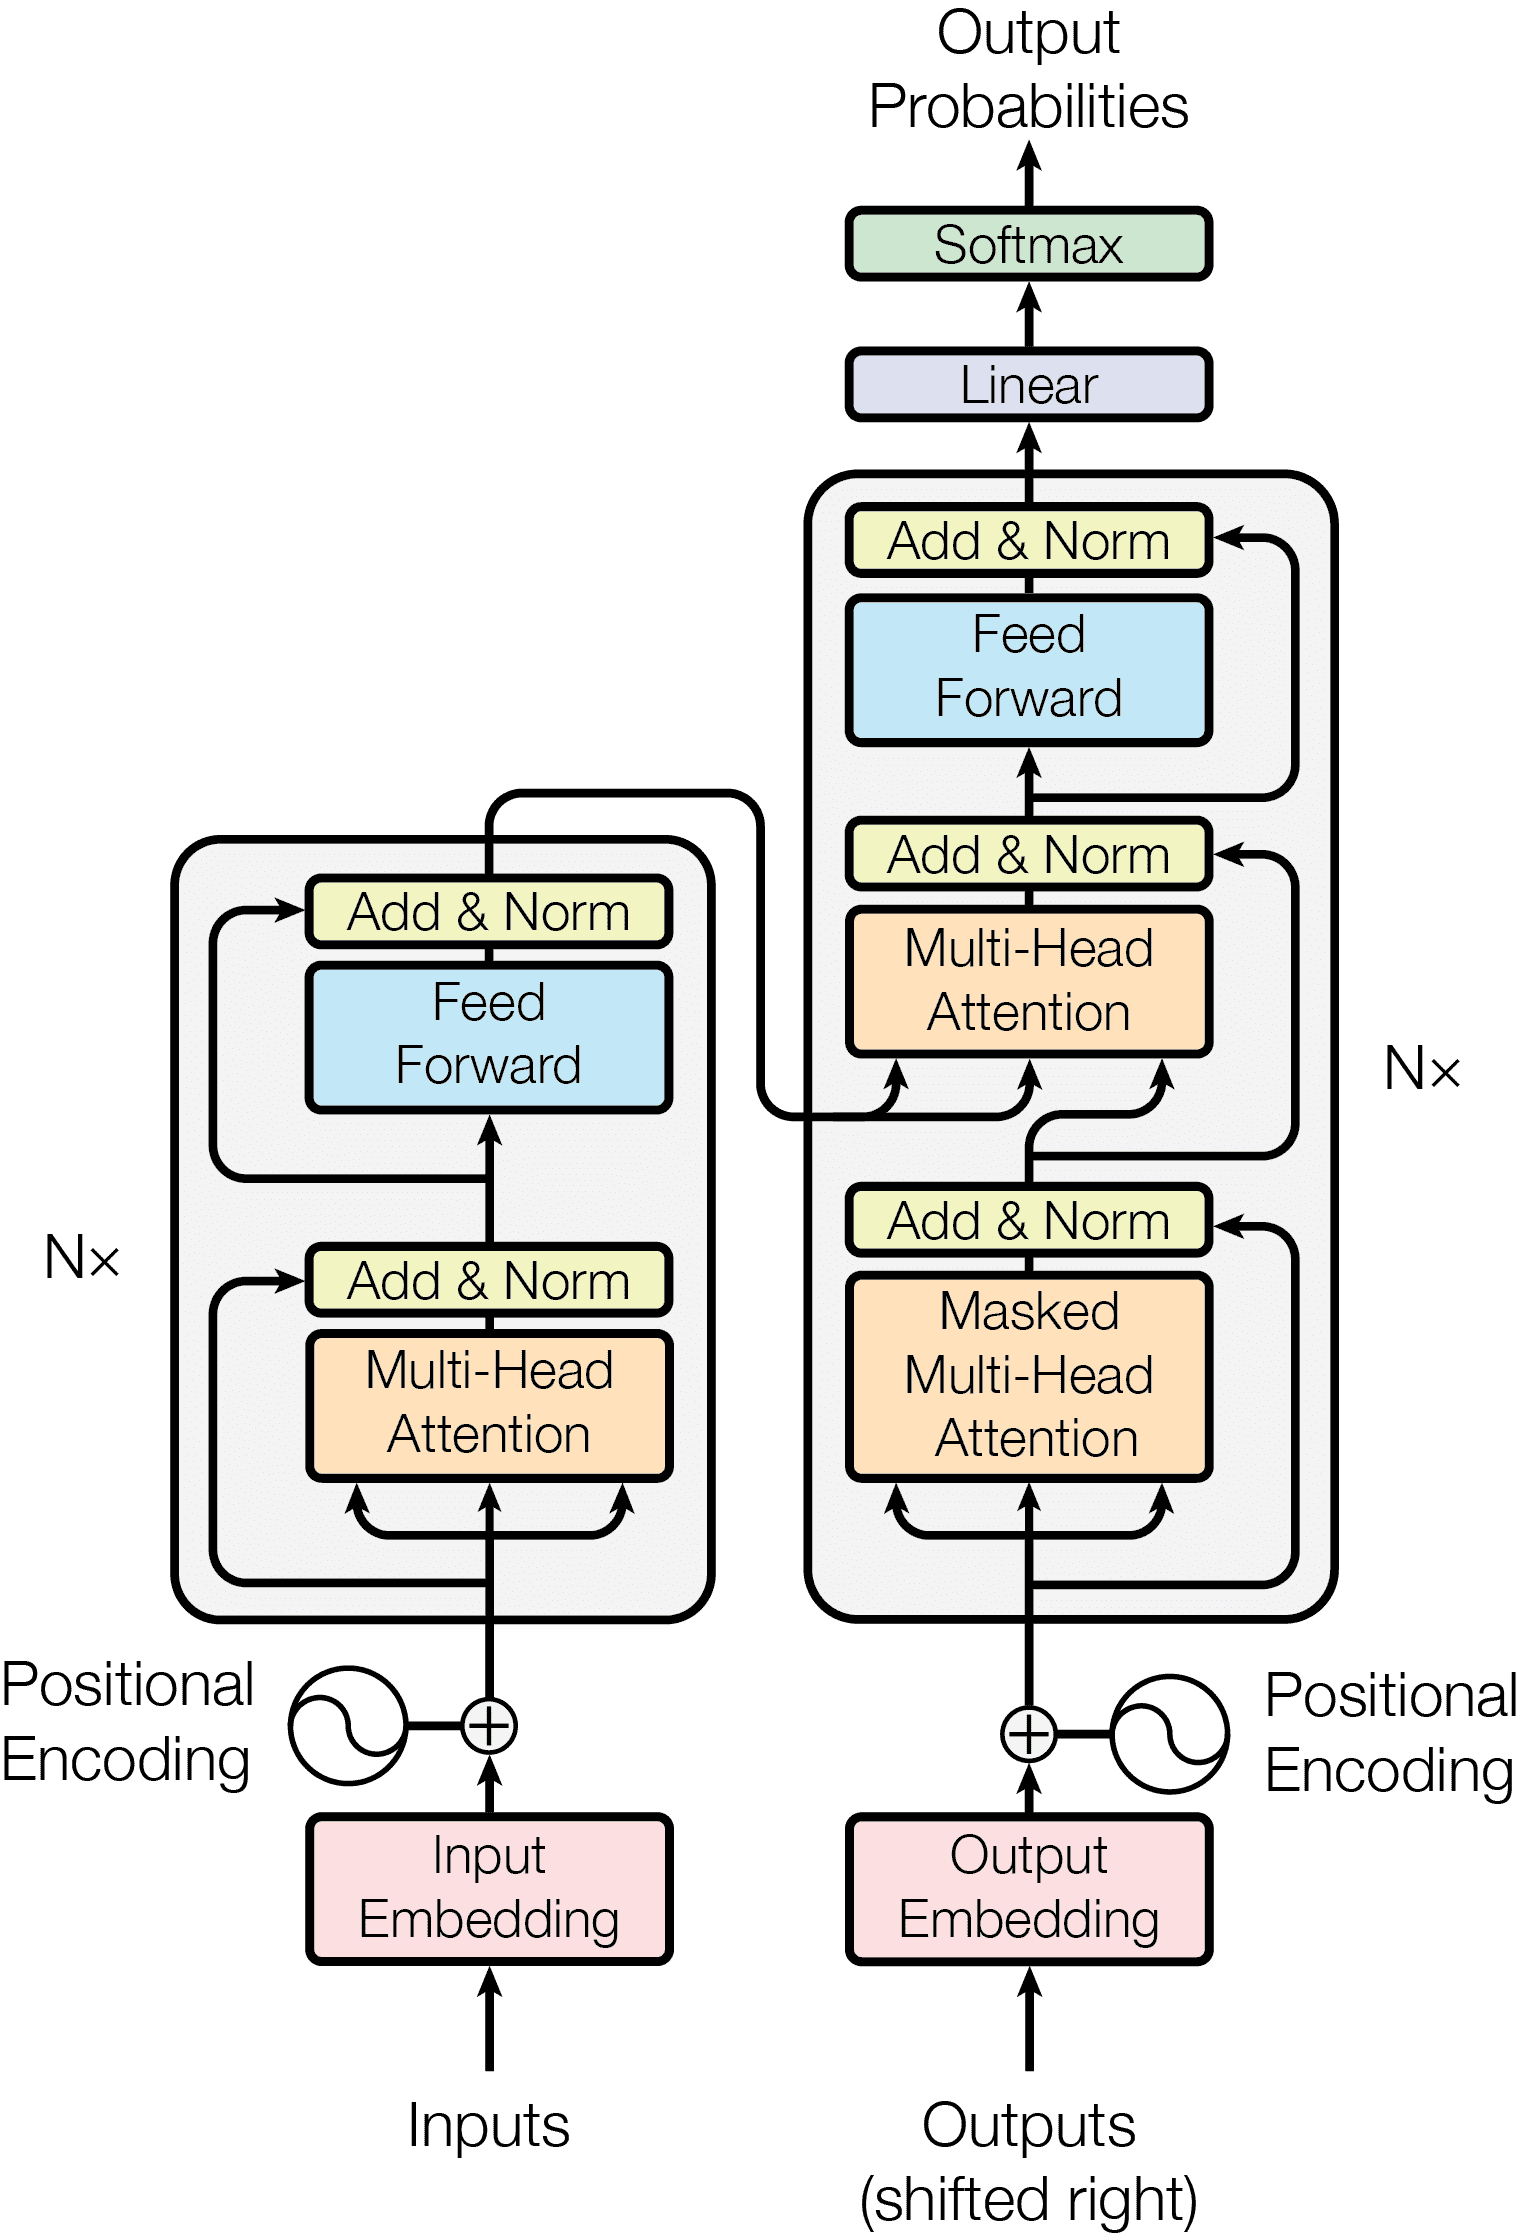
The Transformer - model architecture.
Figure 1 from Attention Is All You Need (Vaswani et al., 2017).

The Transformer is introduced as a transduction model, mainly in the context of machine translation. That is, the model takes a phrase in one language and transforms (transduces) it into another.

Let’s pick an example we’ll follow through the rest of the note:

Ana are mere.pRomanian  ⟶  Ana has apples.English\underset{\text{Romanian}}{\text{Ana are mere.}\vphantom{p}} \;\longrightarrow\; \underset{\text{English}}{\text{Ana has apples.}}

The Model Architecture section of the paper opens with:

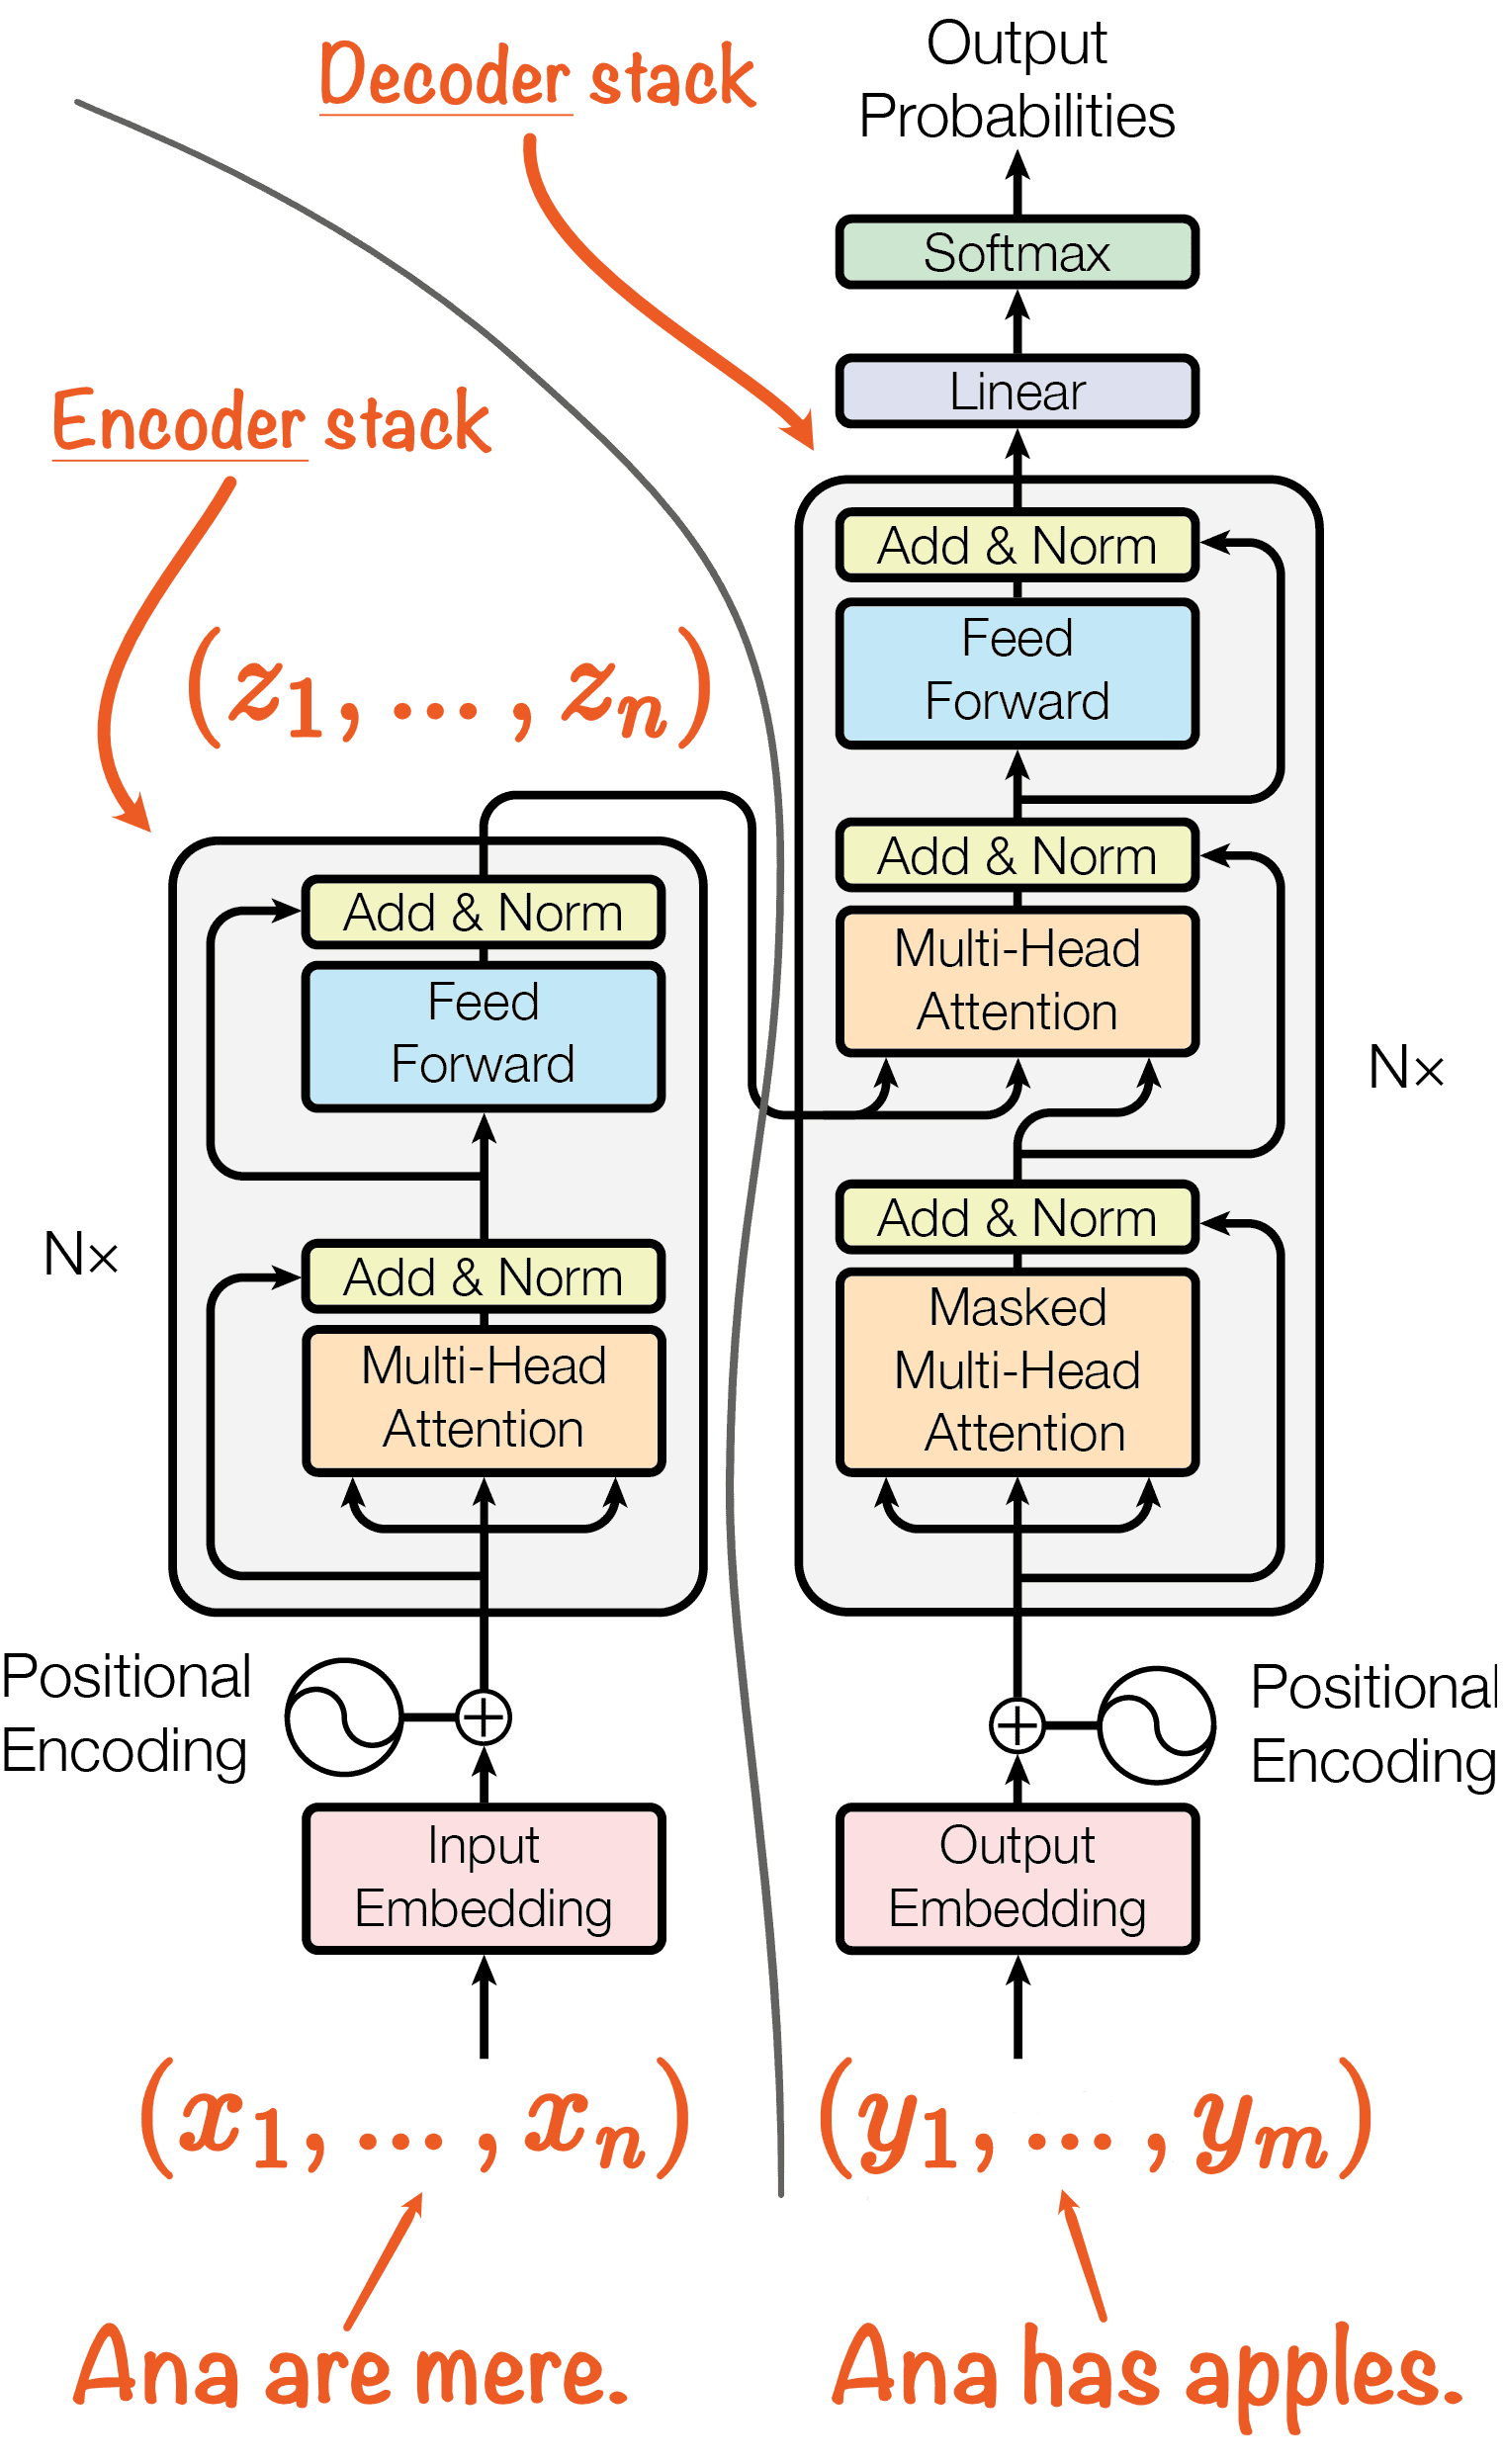
The encoder maps an input sequence of symbol representations (x1,…,xn)(x_1, \ldots, x_n) to a sequence of continuous representations z=(z1,…,zn)\mathbf{z} = (z_1, \ldots, z_n). Given z\mathbf{z}, the decoder then generates an output sequence (y1,…,ym)(y_1, \ldots, y_m) of symbols one element at a time. At each step the model is auto-regressive, consuming the previously generated symbols as additional input when generating the next.

Encoder and decoder, huh? In plain language, as part of this transformation, the Romanian input is encoded by the model into an internal representation, which is then decoded into English, one word at a time.

Let’s put this on the diagram. You can see the two halves: where the input goes in, what produces the internal representation, and where the output comes out.

Transformer stacks with inputs and outputs

The z=(z1,…,zn)\mathbf{z} = (z_1, \ldots, z_n) at the top of the encoder is that internal representation, often called the latent (hidden) representation. There are no words there, only a list of vectors that capture the phrase’s meaning rather than its spelling.

The annotations look backward: Output arrows go into the Transformer but somehow that’s considered the output? We’ll solve that after a short detour.

GPT

In the intro, I drew a timeline from the Transformer to ChatGPT-like LLMs. Before it becomes confusing, I need to draw a line from machine translation models to chat and agentic models.

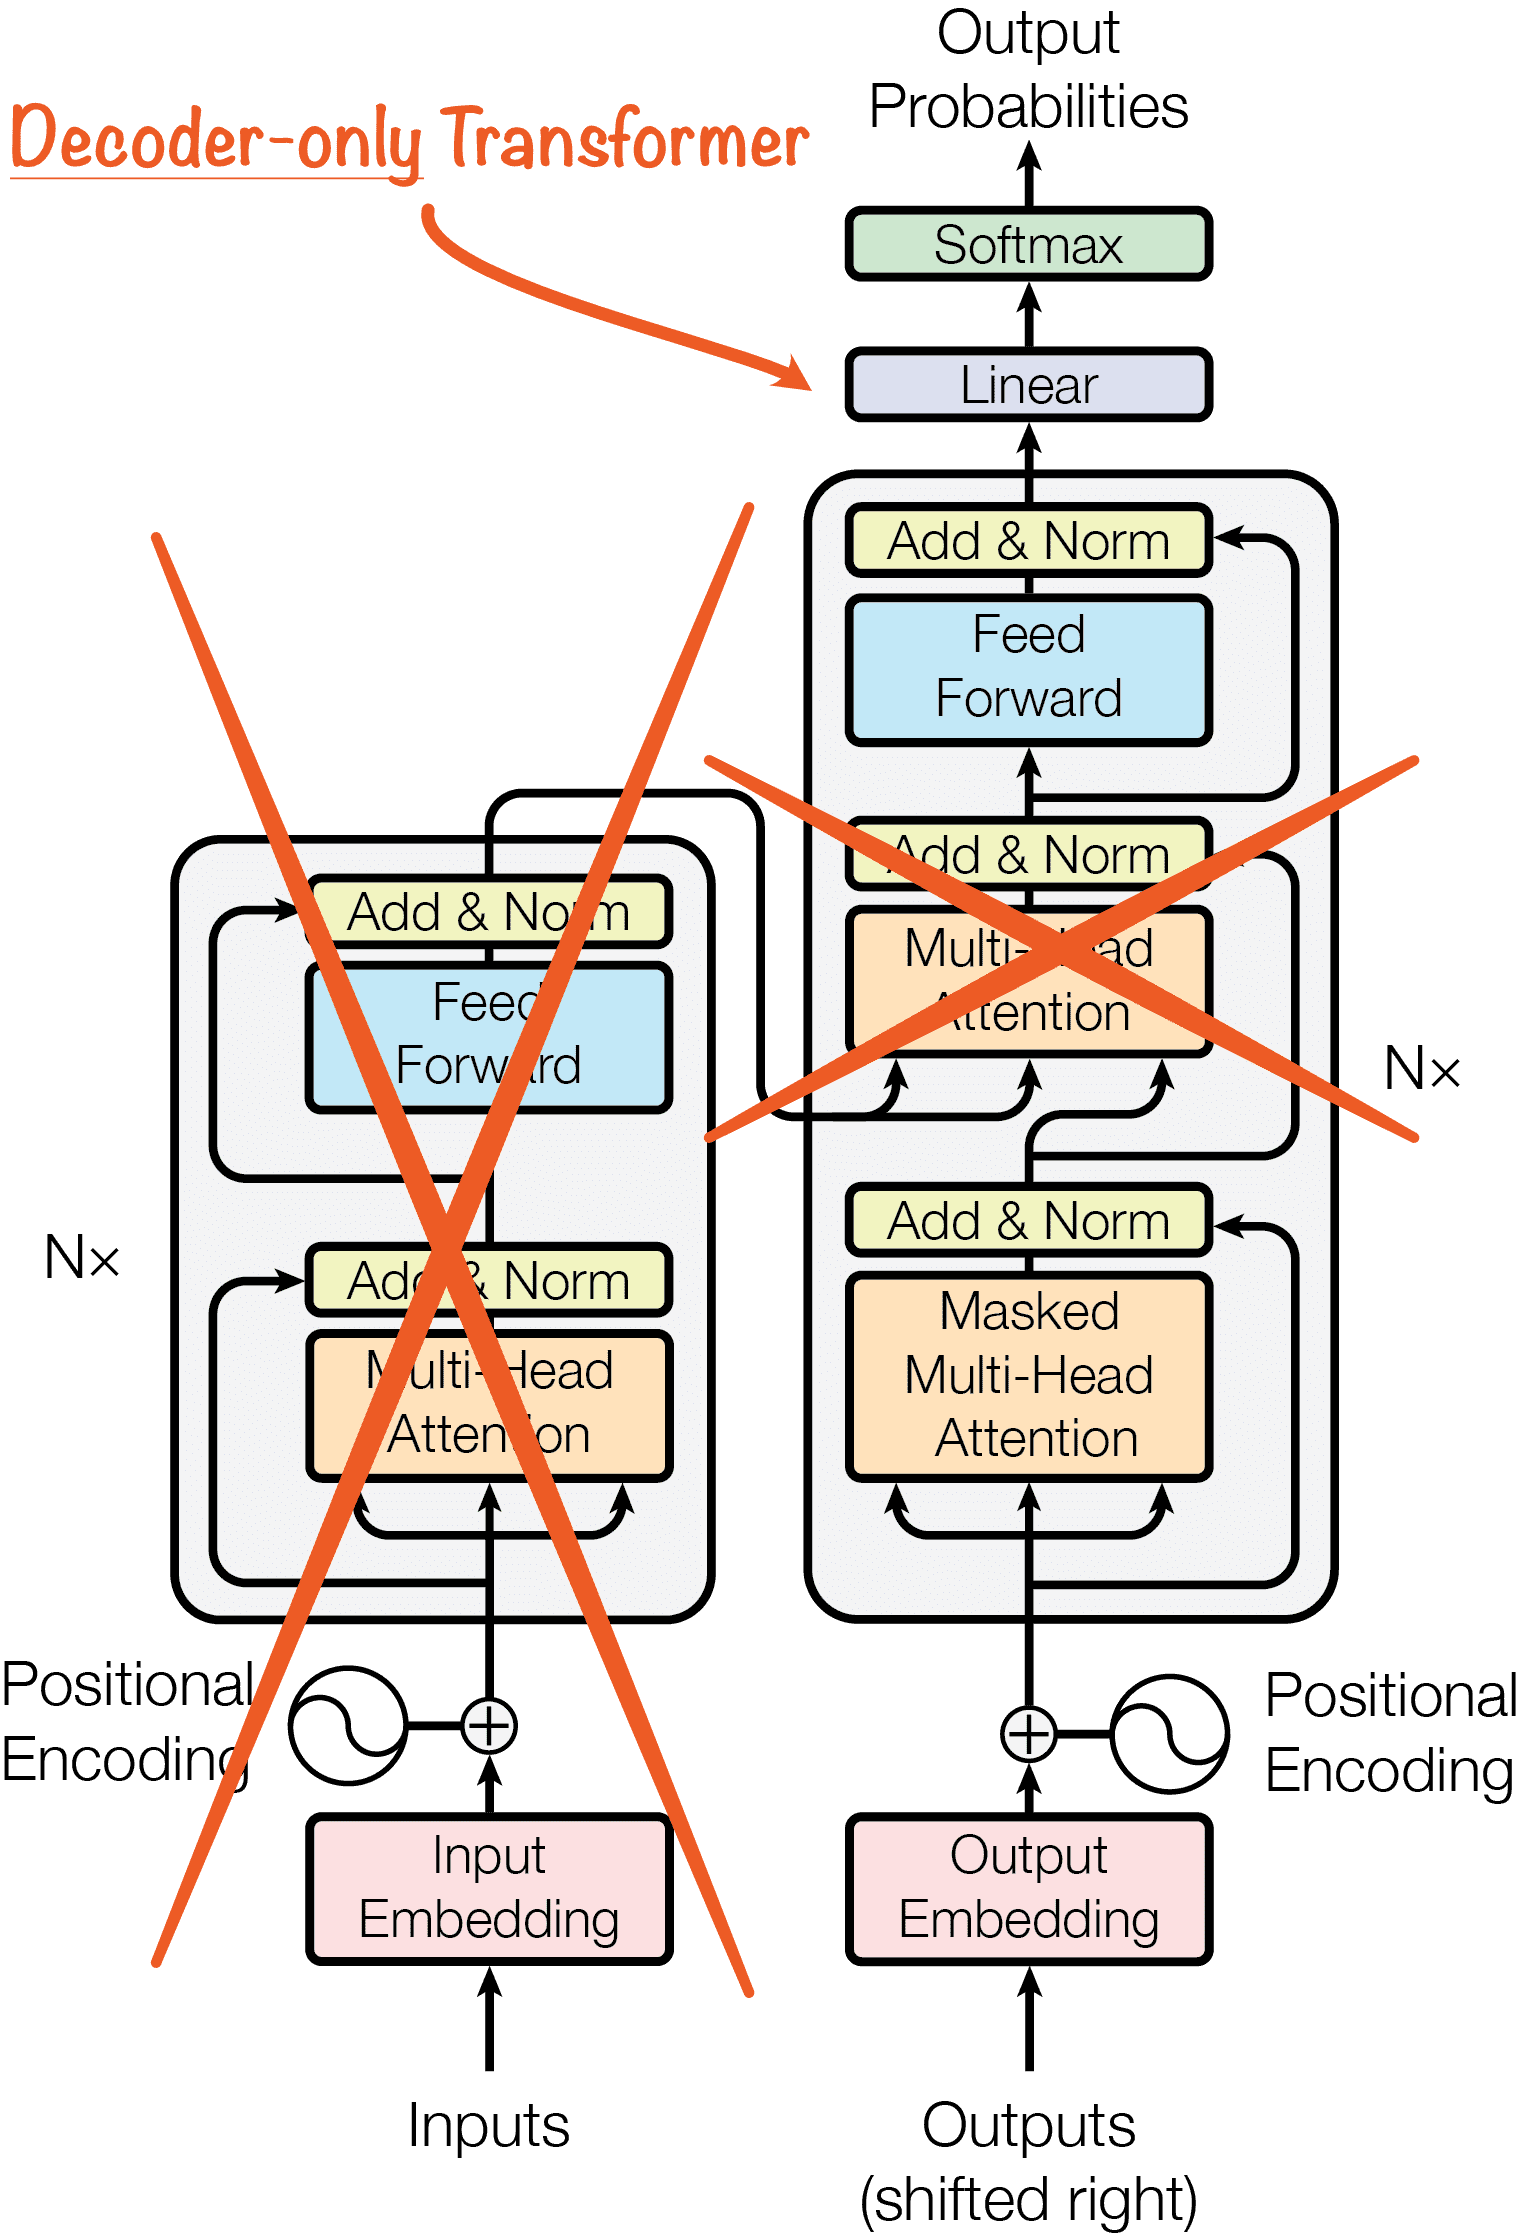
In chat and agentic models, we don’t want our input to be transformed. We want the model to respond to it. To make this happen, we figured we could ignore the encoder side, pass the input as if the decoder wrote it, and let it continue it. We take that newly written output as the model response.

The original ChatGPT and pretty much all LLMs today are built only on the decoder stack of the Transformer, the right side of the diagram above (minus the middle attention that connects it to the encoder). Such models are called decoder-only Transformers. The decoder is the half that generates, which gives us the G and the T in GPT.

From Transformer to Decoder-only Transformer

There’s more though, encoder-only Transformer variants also exist and are actively used for tasks such as classification, semantic similarity, etc. It is impressive how many problems have been influenced by this paper. We are getting a taste of why it is such a big deal.

I recommend reading the note in order, encoder first, even if you’re here for GPT. We build our understanding step by step, and I’ll often refer back to earlier sections.

Auto-regressive Generation

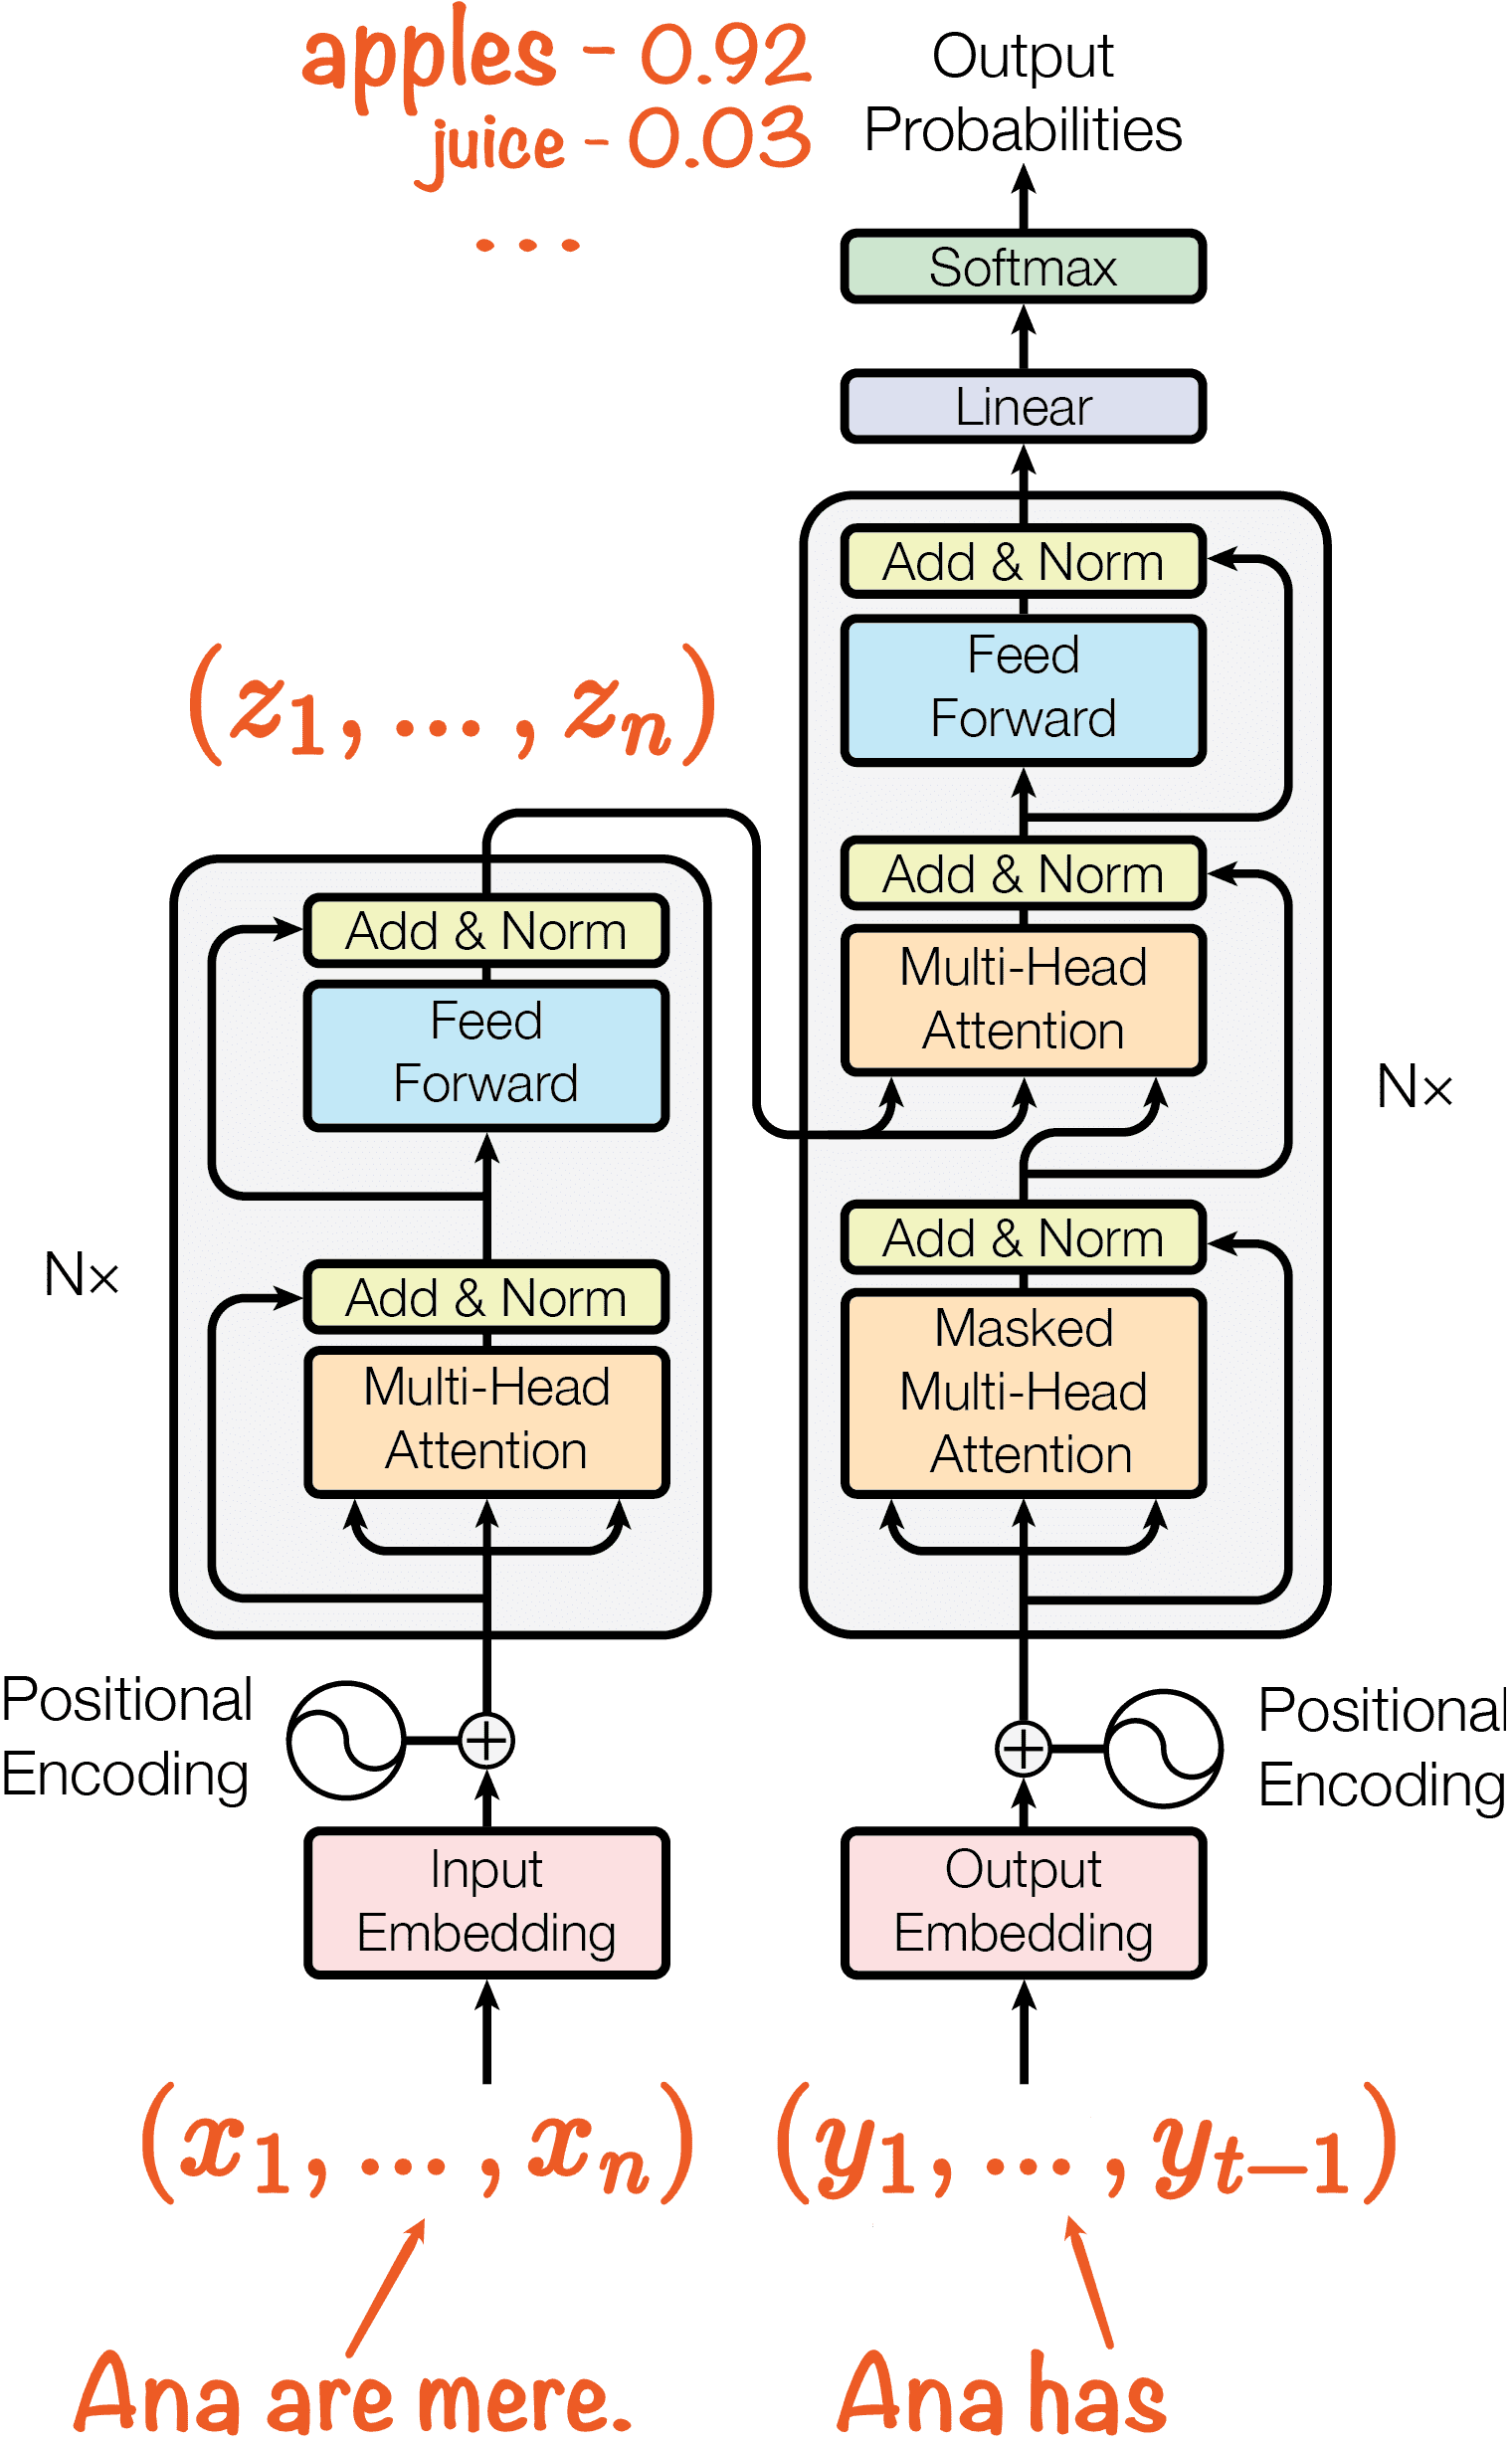
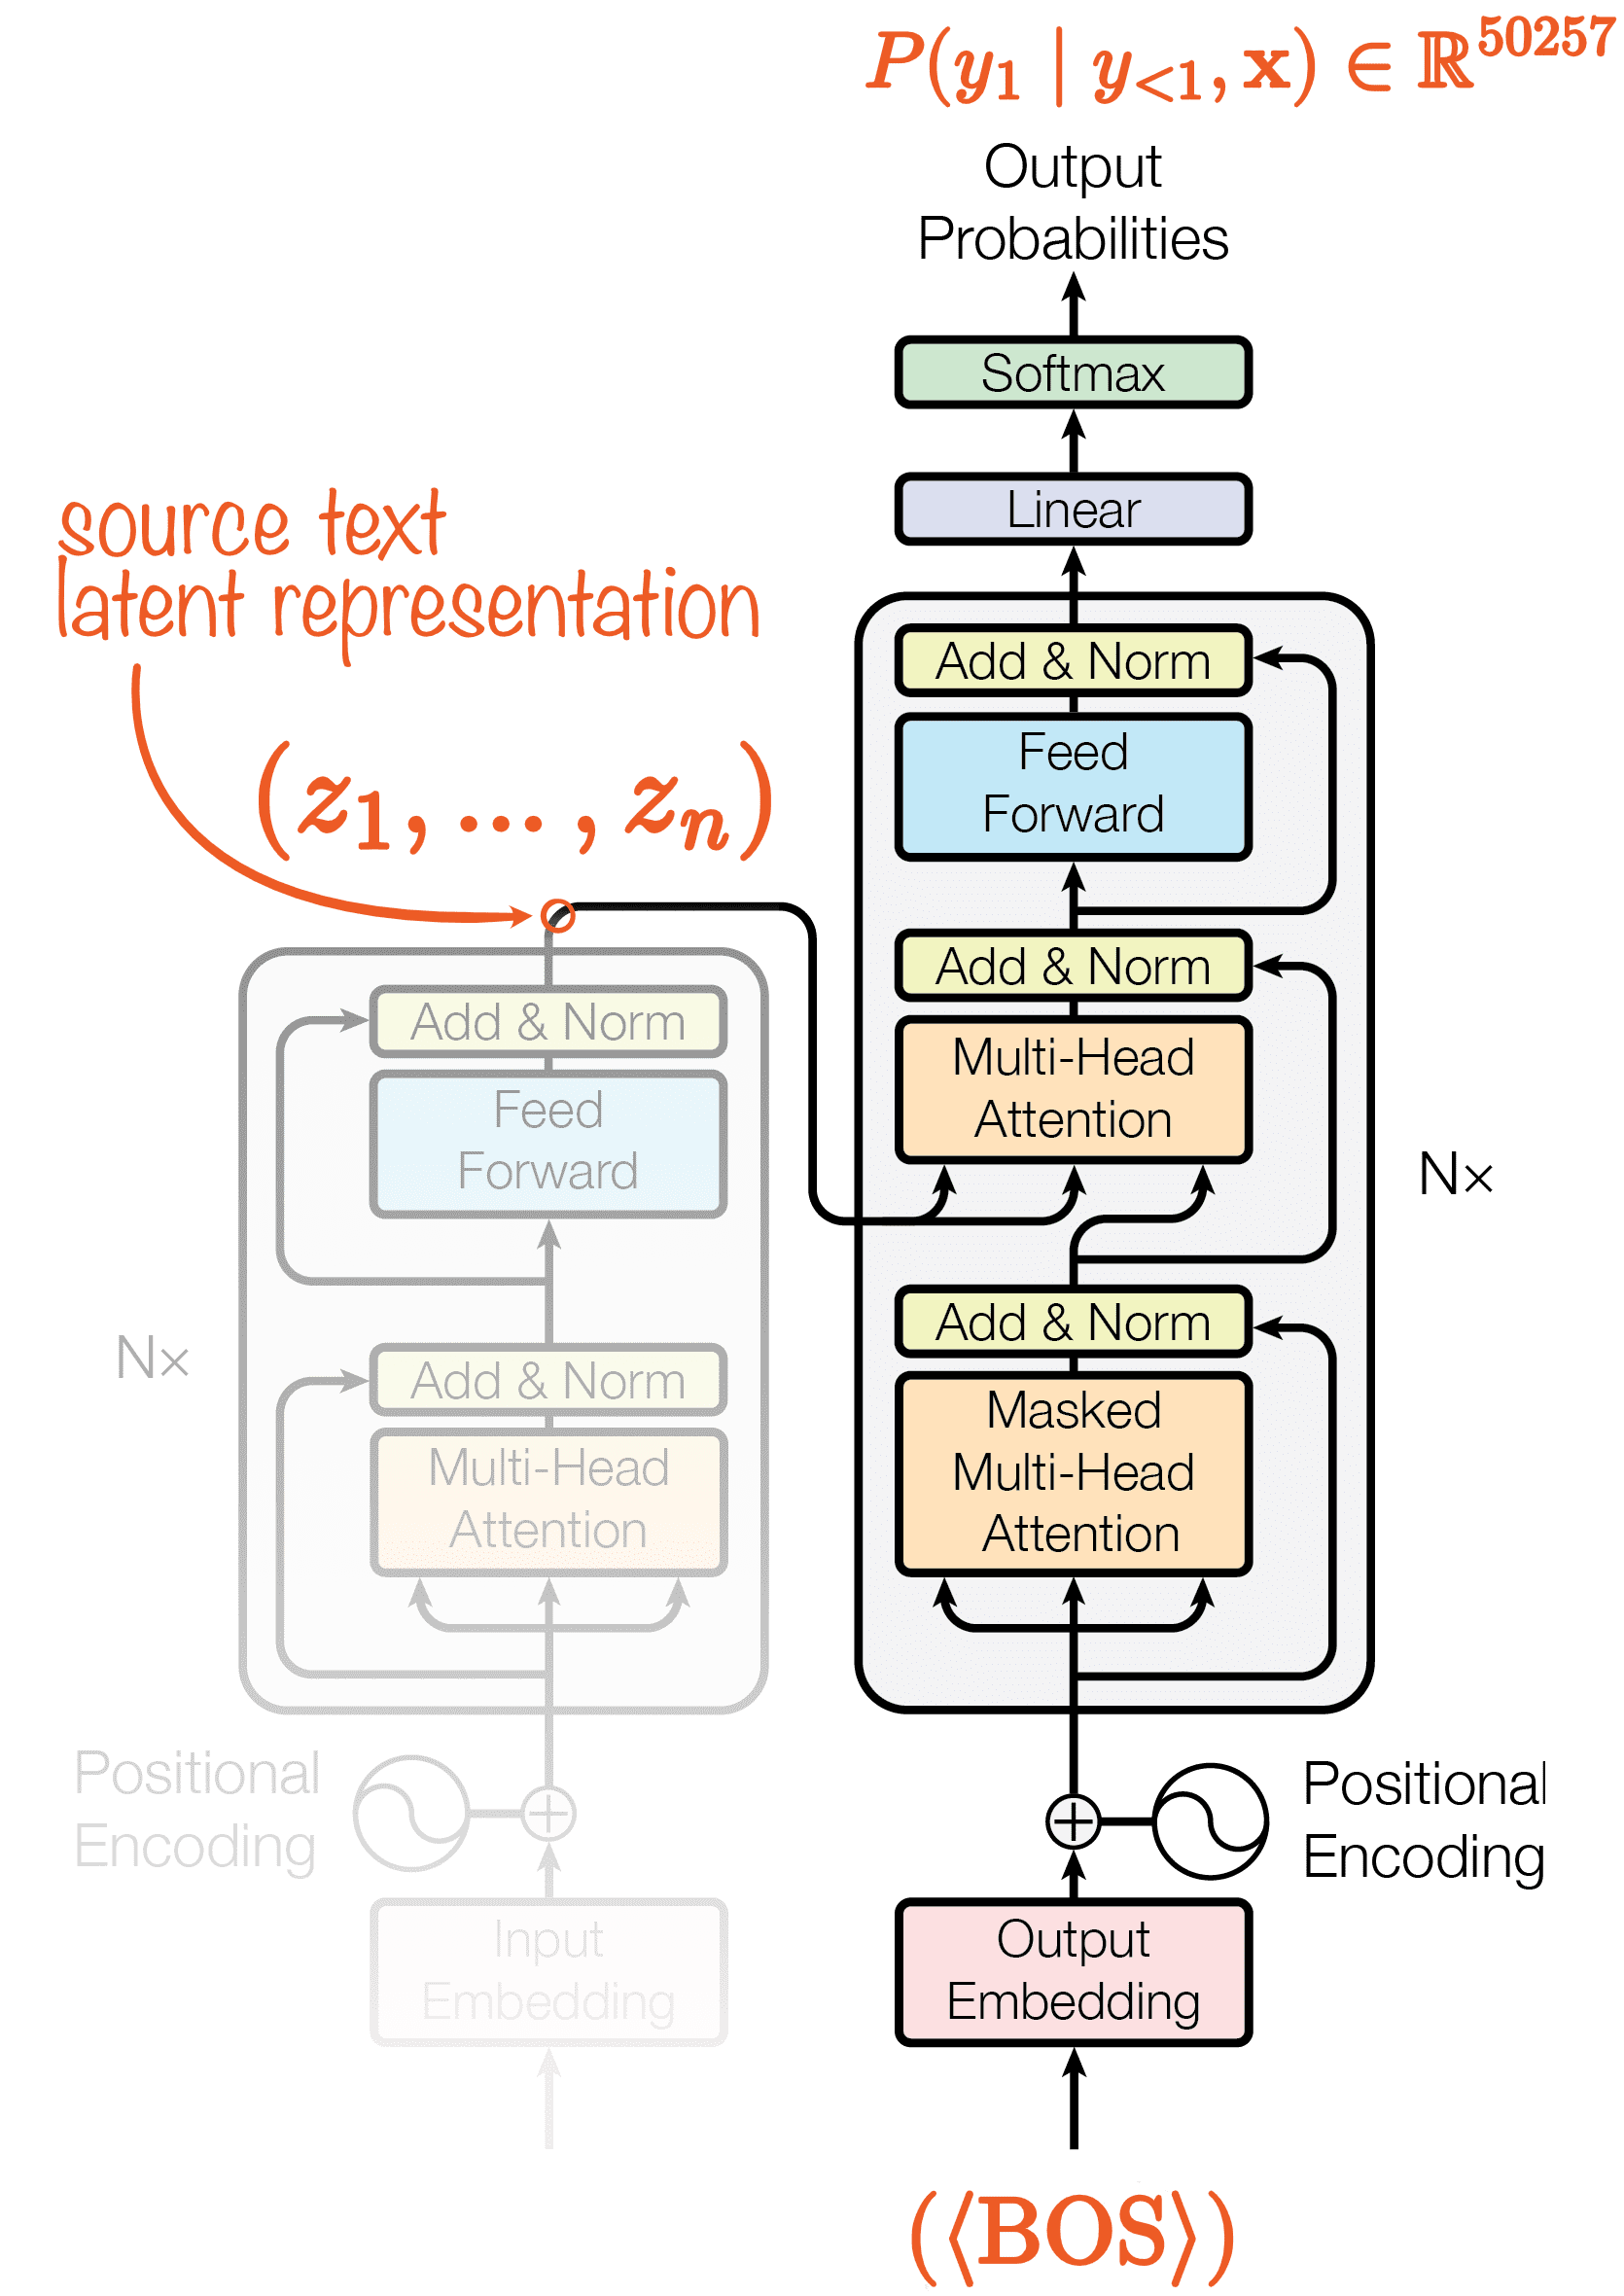
Why do Output arrows go into the Transformer? It makes more sense if we rewind the translation a couple of steps:

Transformer inputs outputs

Remember the last sentence of the opening paragraph of the Model Architecture section:

At each step the model is auto-regressive, consuming the previously generated symbols as additional input when generating the next.

So before the word apples is predicted, we pass the previously generated output Ana has into the model and the model predicts the next word. In this case apples by giving it a probability of 0.92.

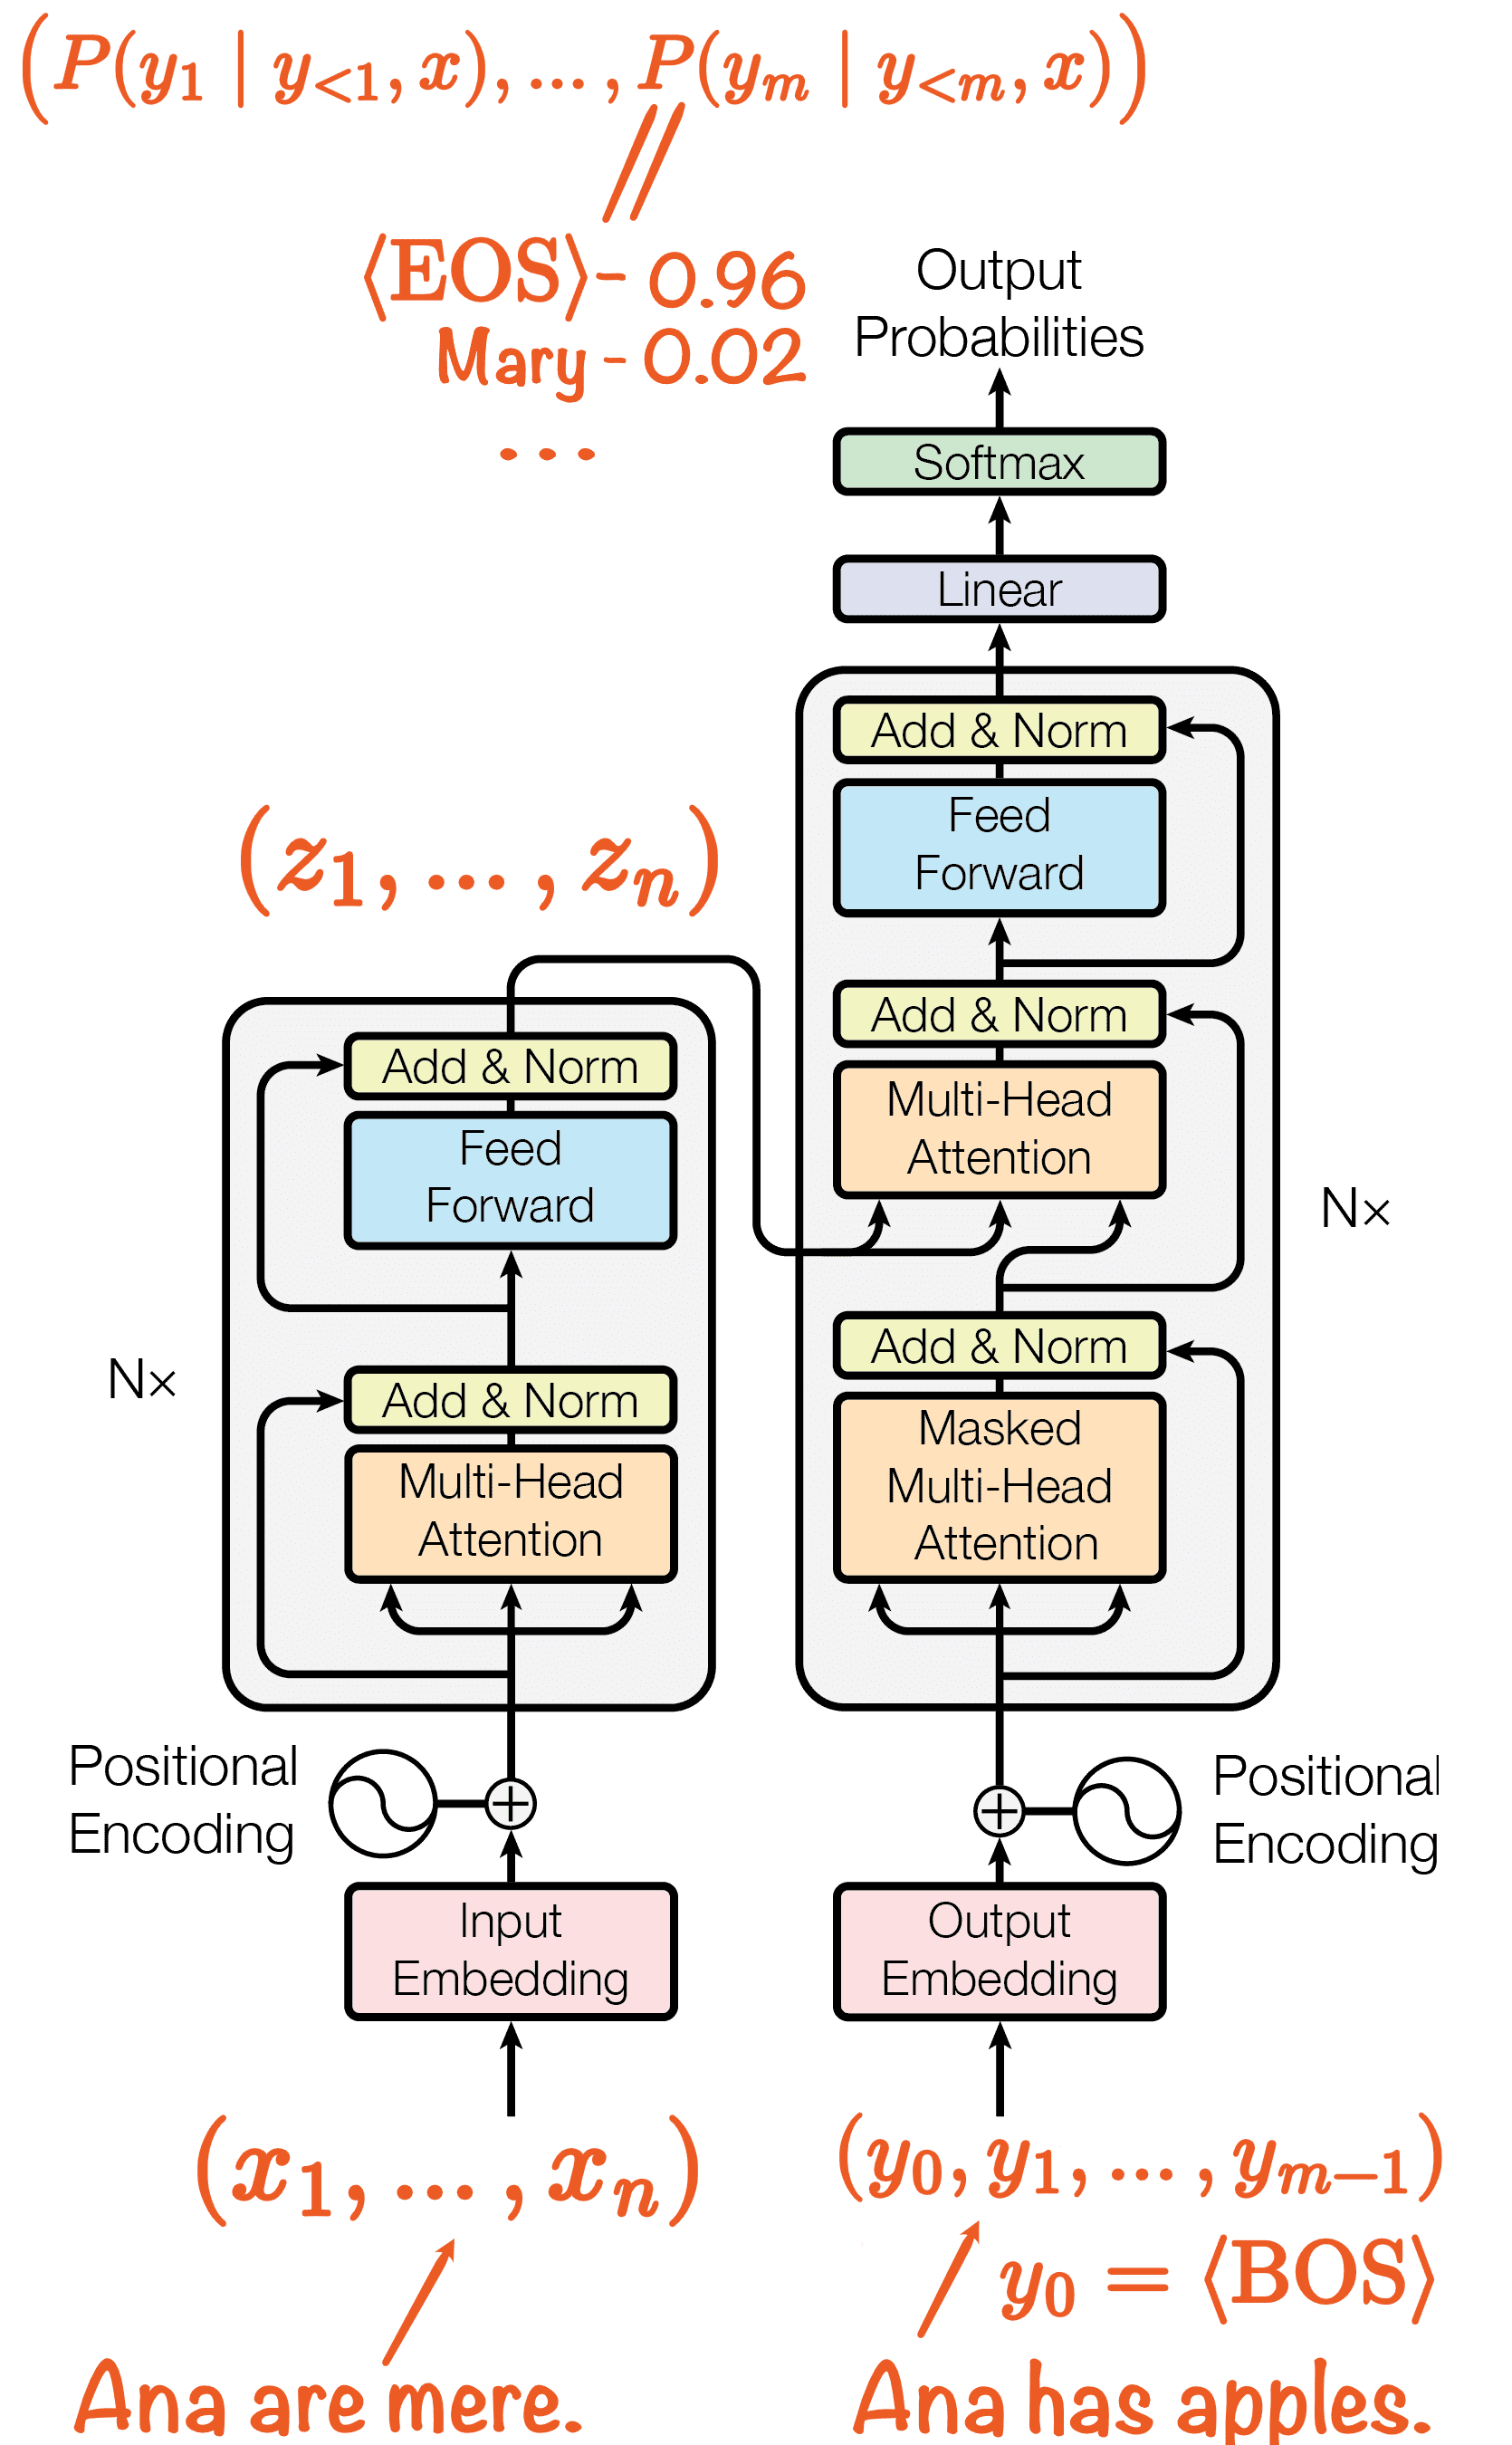
There are three missing details from the diagram to make it complete at this level of abstraction. One of them is probably already on your mind: How do we know when to stop generating new words? For this, we use a special word: EOS (End of Sequence). When the model picks it as the next word, we stop.

The second is that the decoder doesn’t output just one probability distribution for the next word. It outputs one for every position in the output sequence y\mathbf{y}, predicting the word that follows that position.

This creates a chicken-and-egg problem: if every word is predicted from the position before it, where does the first word come from? To solve this, we introduce another special word, the third missing detail: BOS (Beginning of Sequence) and put it in the first position. The distribution at that position gives us the first word.

At this conceptual level, the complete diagram of the last step looks like this:

Transformer inputs outputs full fidelity

Each term P(yi∣y<i,x)P(y_i \mid y_{<i}, \mathbf{x}) at the top is the probability distribution, over every single word the model knows, for position ii, given the output words before it, y<i=(y0,…,yi−1)y_{<i} = (y_0, \ldots, y_{i-1}), and the whole Romanian phrase x\mathbf{x}.

From Text to Numbers

Now that we understand what happens outside the Transformer, let’s start the journey of understanding what’s happening inside. We start with our original phrase, Ana are mere., and see how it makes its way into the encoder (reminder: the left side of the Transformer).

"Ana are mere."→  ?  (x1,…,xn)\texttt{"Ana are mere."} \xrightarrow{\;?\;} (x_1, \ldots, x_n)

I’ve deliberately avoided an exact mapping from the phrase’s words onto xx and yy above, the reason being that they don’t map directly: these models don’t really operate on words. They operate on … tokens. Bingo!

Imagine for a moment that the model operated on words, and think about what the output looks like: a probability distribution over every single word the model knows. How many words are in the English language? In all known languages? Now add misspellings, invented words, numbers, etc. And no matter how long we make the list, someone will type a word that isn’t there. Just thinking about this causes a headache, and it only gets worse as we look inside the model.

The trick is to find something that can be used to build all possible words. But it can’t be too small, or that causes other issues.

That is the tokenization problem.

Here, I won’t get into its details and will use GPT-2’s tokenizer, r50k_base. It’s based on byte-pair encoding (BPE), similar to what the paper used for English-German translation.

r50k_base has a list of 50257 tokens, its vocabulary. The position of a token in this list is its token ID. These IDs are what the x\mathbf{x} and y\mathbf{y} sequences are made of.

"Ana are mere."↓ tokenize(An,a,␣are,␣mere,.)↓ as IDsx=(2025x1,64x2,389x3,5019x4,13x5)\begin{array}{c} \texttt{"Ana are mere."} \\ \Big\downarrow \mathrlap{\scriptstyle\ \text{tokenize}} \\ (\texttt{An}, \texttt{a}, \texttt{\char"2423{}are}, \texttt{\char"2423{}mere}, \texttt{.}) \\ \Big\downarrow \mathrlap{\scriptstyle\ \text{as IDs}} \\ \mathllap{\mathbf{x} = {}} (\underset{x_1}{2025}, \underset{x_2}{64}, \underset{x_3}{389}, \underset{x_4}{5019}, \underset{x_5}{13}) \end{array}
From text to tokens in Python (click to open)
# tokens.py
import tiktoken

enc = tiktoken.get_encoding("r50k_base")
text = "Ana are mere."
ids = enc.encode(text)
tokens = [enc.decode_single_token_bytes(i).decode(errors="replace") for i in ids]
print(f"{text!r}: {tokens} -> {ids}")
uv run --with tiktoken python tokens.py
'Ana are mere.': ['An', 'a', ' are', ' mere', '.'] -> [2025, 64, 389, 5019, 13]

For the output, we will go the other way: pick a token ID from each probability distribution, then turn the IDs back into text.

Note: r50k_base has no separate ⟨BOS⟩\langle\text{BOS}\rangle and ⟨EOS⟩\langle\text{EOS}\rangle tokens. One special token, <|endoftext|>, plays both roles.

Through the Encoder

Transformer input embedding

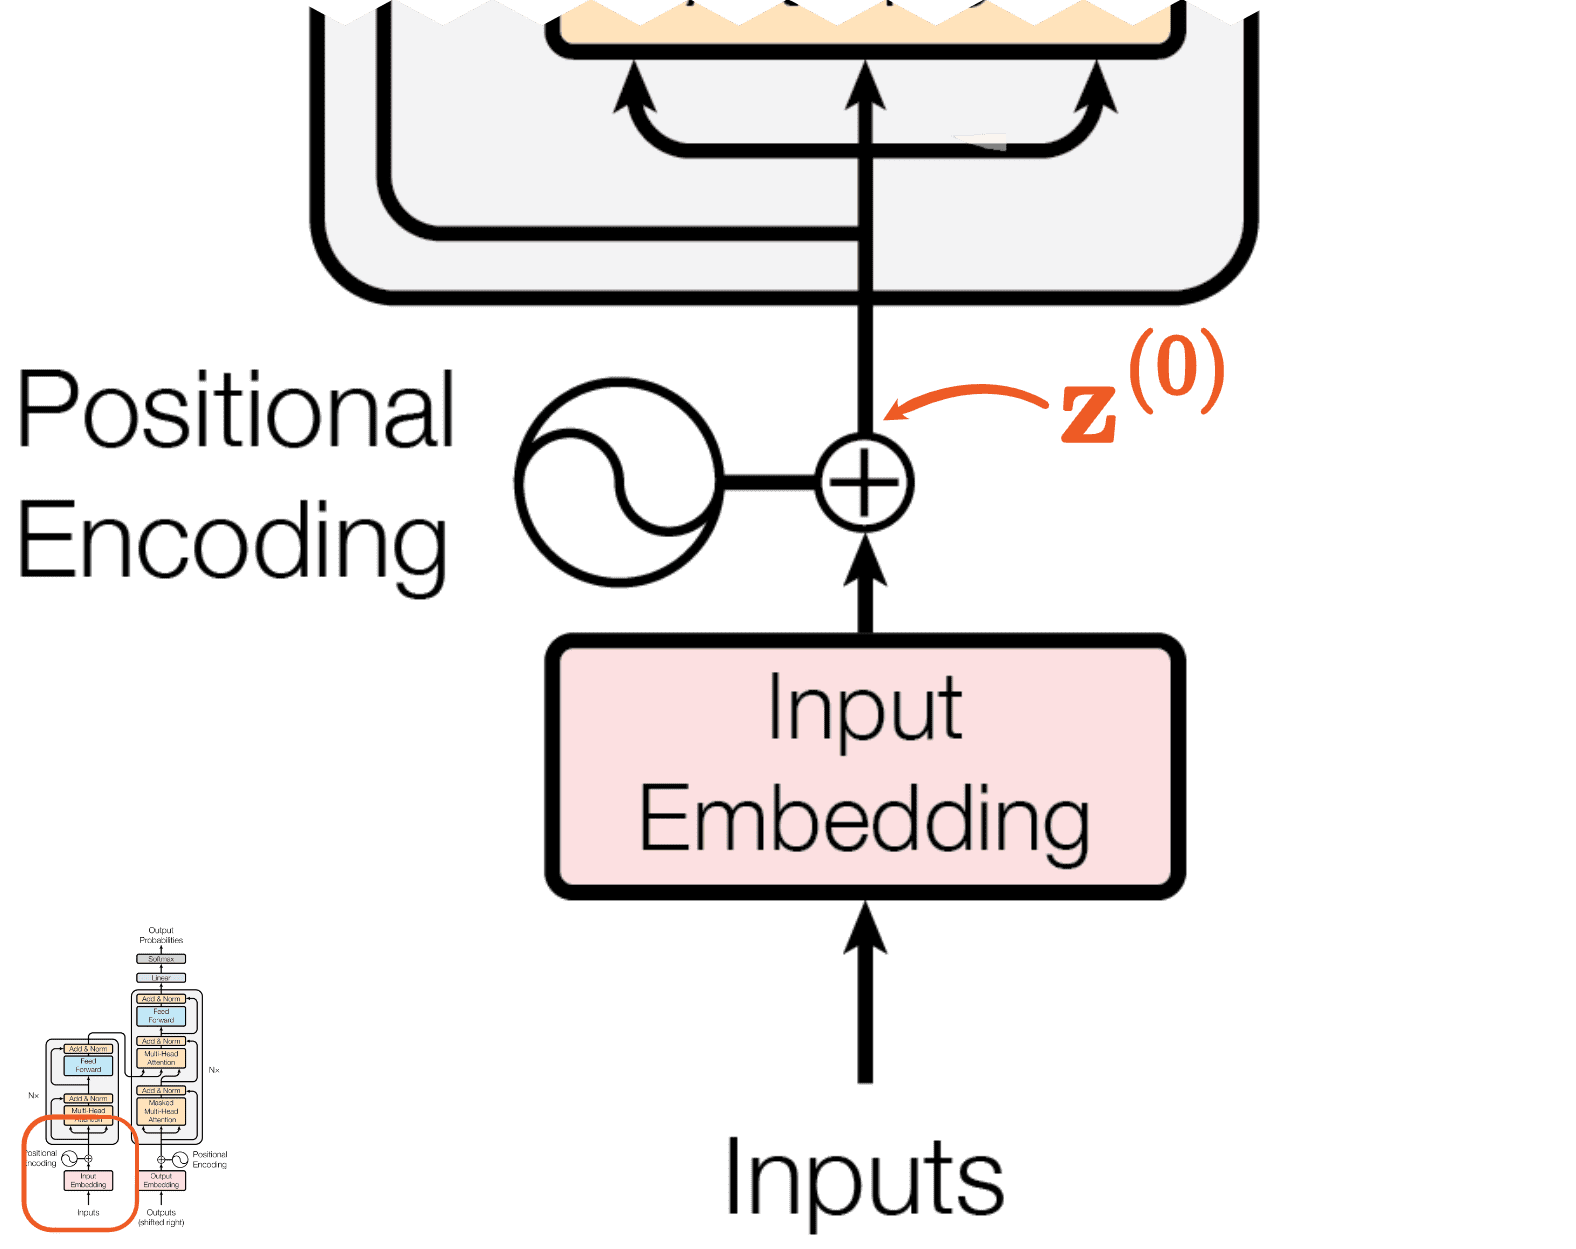
Each token ID is associated with a vector. In the paper, the size of these vectors is dmodel=512d_\text{model} = 512 (Sections 3.1 and 3.4). Stacked together, they form the embedding matrix E∈R50257×512E \in \mathbb{R}^{50257 \times 512}, one row per token ID. In the diagram, this matrix is the Input Embedding box. This is the first time we meet some of the model parameters—numbers the model learns.

The box next to it, Positional Encoding, is a list of vectors too, this time one per position; we’ll call this matrix PEPE. Unlike the embeddings, they are computed from the token positions rather than learned. These vectors are what let the encoder distinguish between two different arrangements of the same tokens. That’s all we need for the purpose of this note; see Section 3.5 Positional Encoding of the paper for details.

Back to our example, Ana are mere.: for each token, we look up its learned embedding (its row of EE), add the positional encoding for its position (a row of PEPE), and get the encoder input, our first hidden state z(0)\mathbf{z}^{(0)}:

[E2025z1(0)E64z1(0)E389z1(0)E5019z1(0)E13z1(0)]⏟embeddings+[PE0z1(0)PE1z1(0)PE2z1(0)PE3z1(0)PE4z1(0)]⏟positions=[z1(0)z1(0)z2(0)z1(0)z3(0)z1(0)z4(0)z1(0)z5(0)z1(0)]⏟z(0)∈R5×512\def\rowvec#1{\mathrlap{\rule[0.5ex]{1em}{0.4pt}}\hspace{0.28em} & #1\vphantom{z^{(0)}_1} & \hspace{0.28em}\mathllap{\rule[0.5ex]{1em}{0.4pt}}} \underbrace{\begin{bmatrix} \rowvec{E_{2025}} \\ \rowvec{E_{64}} \\ \rowvec{E_{389}} \\ \rowvec{E_{5019}} \\ \rowvec{E_{13}} \end{bmatrix}}_{\text{embeddings}} + \underbrace{\begin{bmatrix} \rowvec{PE_0} \\ \rowvec{PE_1} \\ \rowvec{PE_2} \\ \rowvec{PE_3} \\ \rowvec{PE_4} \end{bmatrix}}_{\text{positions}} = \underbrace{\begin{bmatrix} \rowvec{z^{(0)}_1} \\ \rowvec{z^{(0)}_2} \\ \rowvec{z^{(0)}_3} \\ \rowvec{z^{(0)}_4} \\ \rowvec{z^{(0)}_5} \end{bmatrix}}_{\mathbf{z}^{(0)} \in \mathbb{R}^{5 \times 512}}

Note: positions count from 0, as in the paper’s code, so the first token x1x_1 gets PE0PE_0.

The result z(0)\mathbf{z}^{(0)} is a table of numbers with one row per token and 512 numbers per row. Numbers are made up.

z(0)=[0.120.520.91⋯z1(0)1.330.571.190.68⋯z1(0)0.481.35−0.340.21⋯z1(0)1.19−0.47−1.340.52⋯z1(0)1.88−0.710.07−1.05⋯z1(0)0.79]⏞512 numbers per row←z1(0)An←z2(0)a←z3(0)␣are←z4(0)␣mere←z5(0).\mathbf{z}^{(0)} = \overbrace{\begin{bmatrix*}[r] 0.12 & 0.52 & 0.91 & \cdots\vphantom{z^{(0)}_1} & 1.33 \\ 0.57 & 1.19 & 0.68 & \cdots\vphantom{z^{(0)}_1} & 0.48 \\ 1.35 & -0.34 & 0.21 & \cdots\vphantom{z^{(0)}_1} & 1.19 \\ -0.47 & -1.34 & 0.52 & \cdots\vphantom{z^{(0)}_1} & 1.88 \\ -0.71 & 0.07 & -1.05 & \cdots\vphantom{z^{(0)}_1} & 0.79 \end{bmatrix*}}^{512 \text{ numbers per row}} \begin{array}{ll} \leftarrow z^{(0)}_1 & \texttt{An} \\ \leftarrow z^{(0)}_2 & \texttt{a} \\ \leftarrow z^{(0)}_3 & \texttt{\char"2423{}are} \\ \leftarrow z^{(0)}_4 & \texttt{\char"2423{}mere} \\ \leftarrow z^{(0)}_5 & \texttt{.} \end{array}

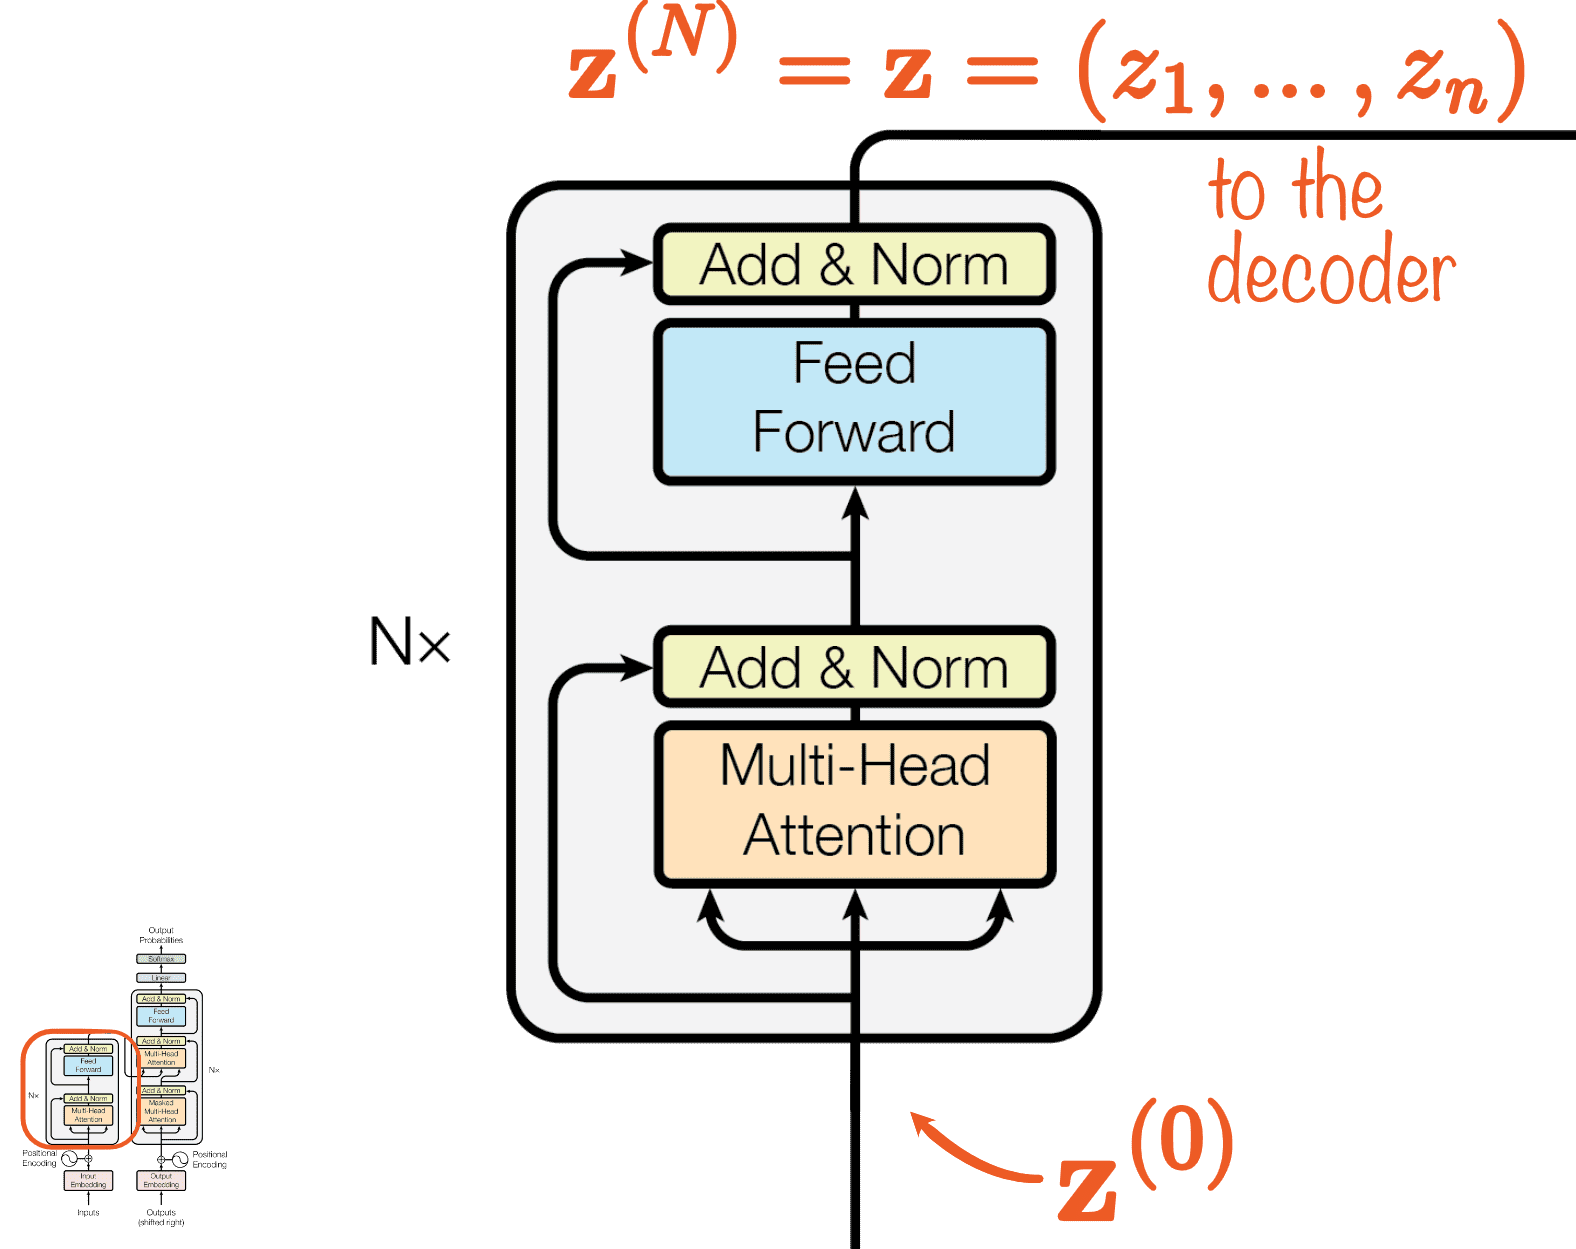
This hidden state makes its way into the encoder stack, which in the paper has N=6N = 6 layers.

We’ll denote the output of each layer z(1),…,z(N)\mathbf{z}^{(1)}, \ldots, \mathbf{z}^{(N)}. The output of the last layer is what we referred to as the latent representation, written without a superscript: z=z(6)\mathbf{z} = \mathbf{z}^{(6)}.

Note: capital NN is the number of layers (6), while lowercase nn is the number of tokens (5 for Ana are mere.). The two are unrelated.

Transformer encoder stack

All these outputs have the same size, 5×5125 \times 512. Remember, Ana are mere. has 5 tokens. The 512 is a design choice, a hyperparameter that worked well for the problem at hand.

z(ℓ)=EncoderLayer(z(ℓ−1);θℓ),ℓ=1,…,N\mathbf{z}^{(\ell)} = \text{EncoderLayer}\big(\mathbf{z}^{(\ell-1)}; \theta_\ell\big), \qquad \ell = 1, \ldots, N

Every layer runs the same computation, EncoderLayer\text{EncoderLayer}, with its own parameters θℓ\theta_\ell. That makes two kinds of model parameters so far: EE and the θℓ\theta_\ell.

Inside an Encoder Layer

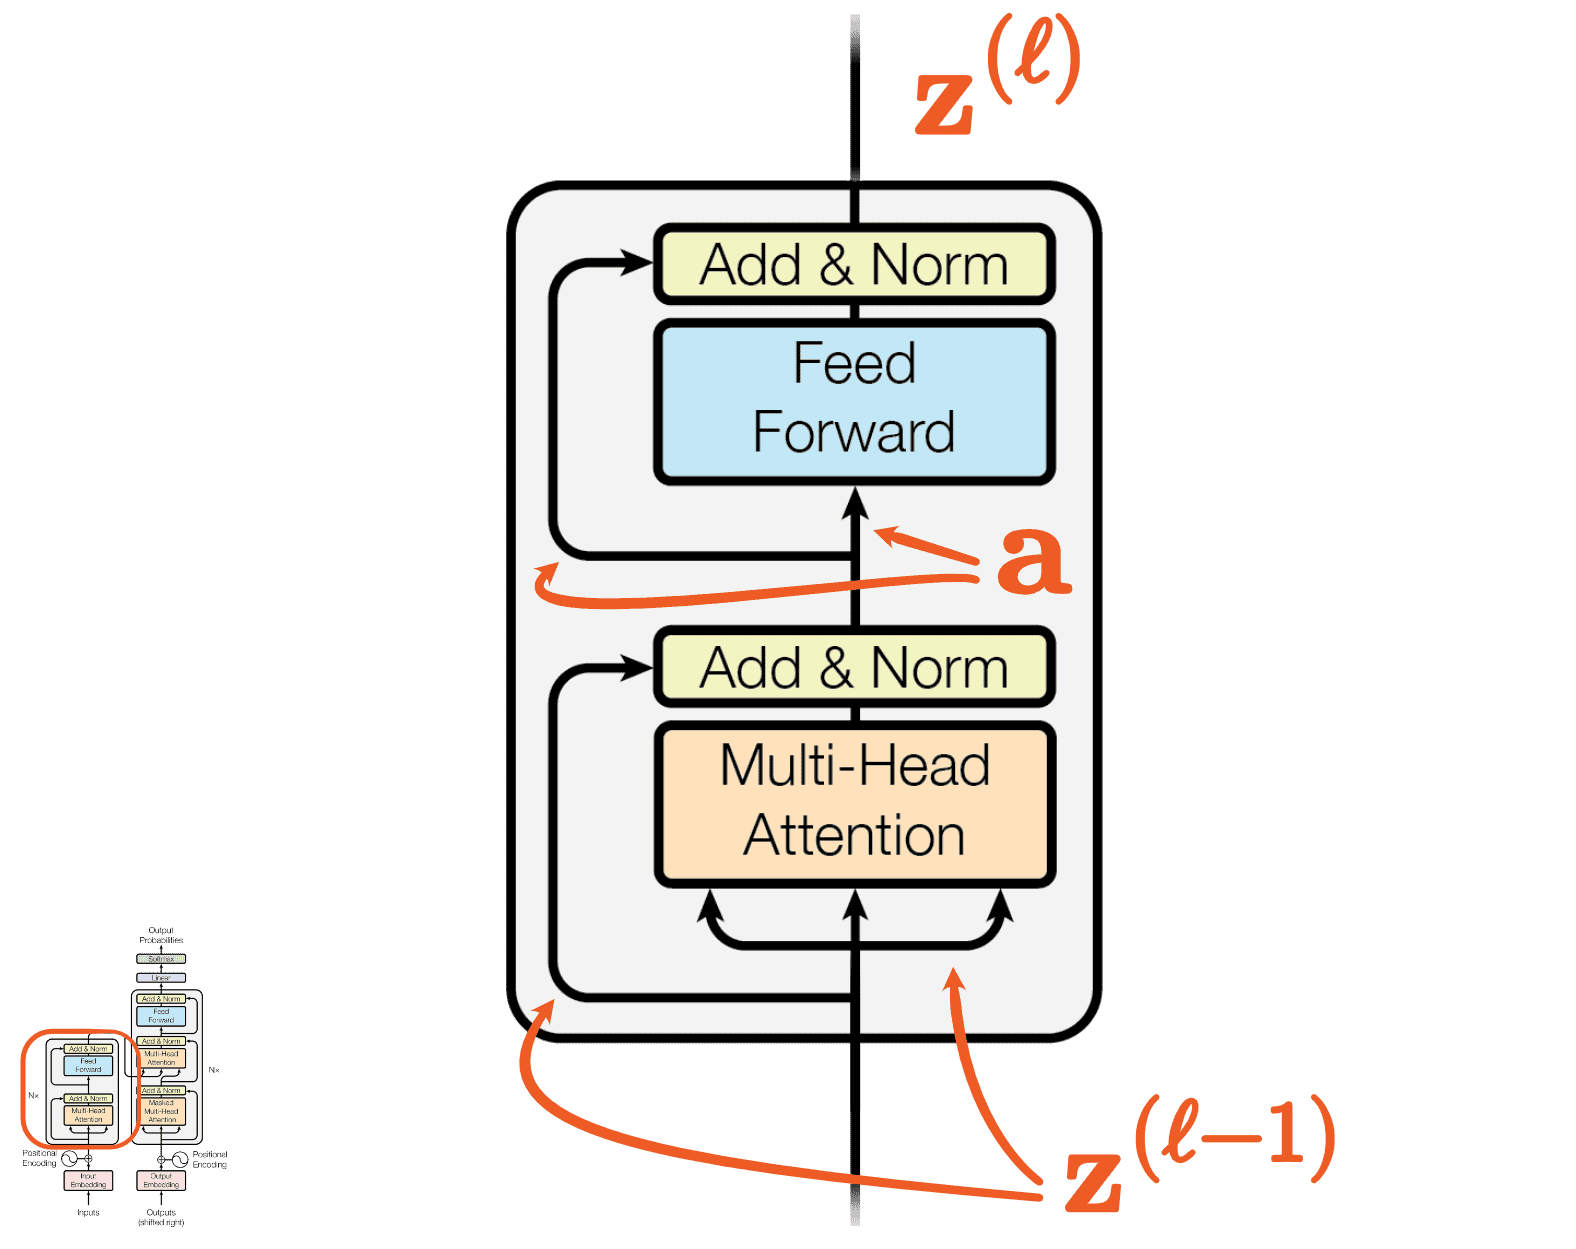
Let’s unwrap EncoderLayer and figure out why there is a 🔱 trident. I still need to squint quite a bit to understand the intention, so don’t worry if it looks confusing at first.

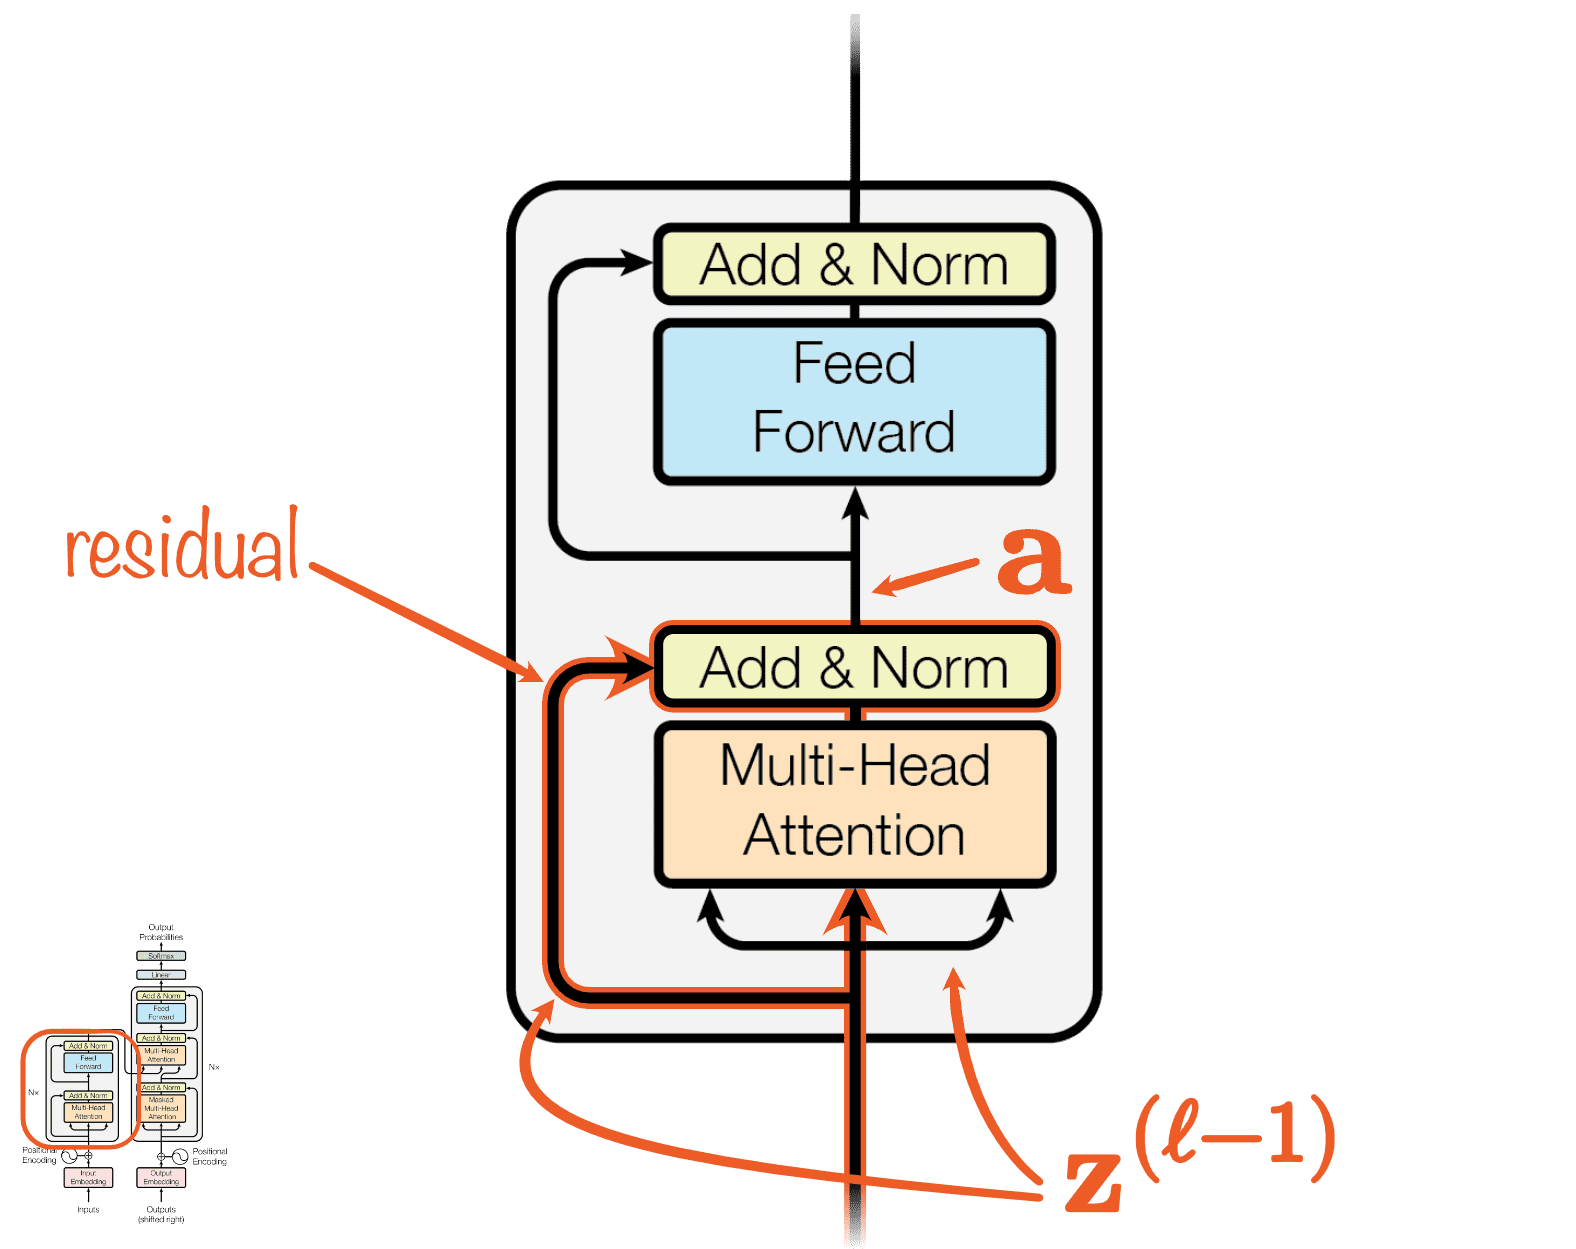
The layer input, z(ℓ−1)\mathbf{z}^{(\ell-1)}, goes through Multi-Head Attention and then Add & Norm, which we’ll unpack later. We’ll name the result a\mathbf{a}. Then a\mathbf{a} goes through Feed Forward and another Add & Norm. The paper calls each pair a sub-layer (Section 3.1), so an encoder layer has two.

Spelling it out:

a=LayerNorm1(z(ℓ−1)+MultiHead(z(ℓ−1),z(ℓ−1),z(ℓ−1)))z(ℓ)=LayerNorm2(a+FFN(a))\def\addnorm#1{\textcolor{b8860b}{#1}} \def\attn#1{\textcolor{e0701a}{#1}} \def\ffn#1{\textcolor{2b8cc4}{#1}} \begin{aligned} \mathbf{a} &= \addnorm{\text{LayerNorm}_1}\big(\mathbf{z}^{(\ell-1)} \mathbin{\addnorm{+}} \attn{\text{MultiHead}}(\mathbf{z}^{(\ell-1)}, \mathbf{z}^{(\ell-1)}, \mathbf{z}^{(\ell-1)})\big) \\ \mathbf{z}^{(\ell)} &= \addnorm{\text{LayerNorm}_2}\big(\mathbf{a} \mathbin{\addnorm{+}} \ffn{\text{FFN}}(\mathbf{a})\big) \end{aligned}

Transformer encoder layer

Two Eight Heads Are Better Than One

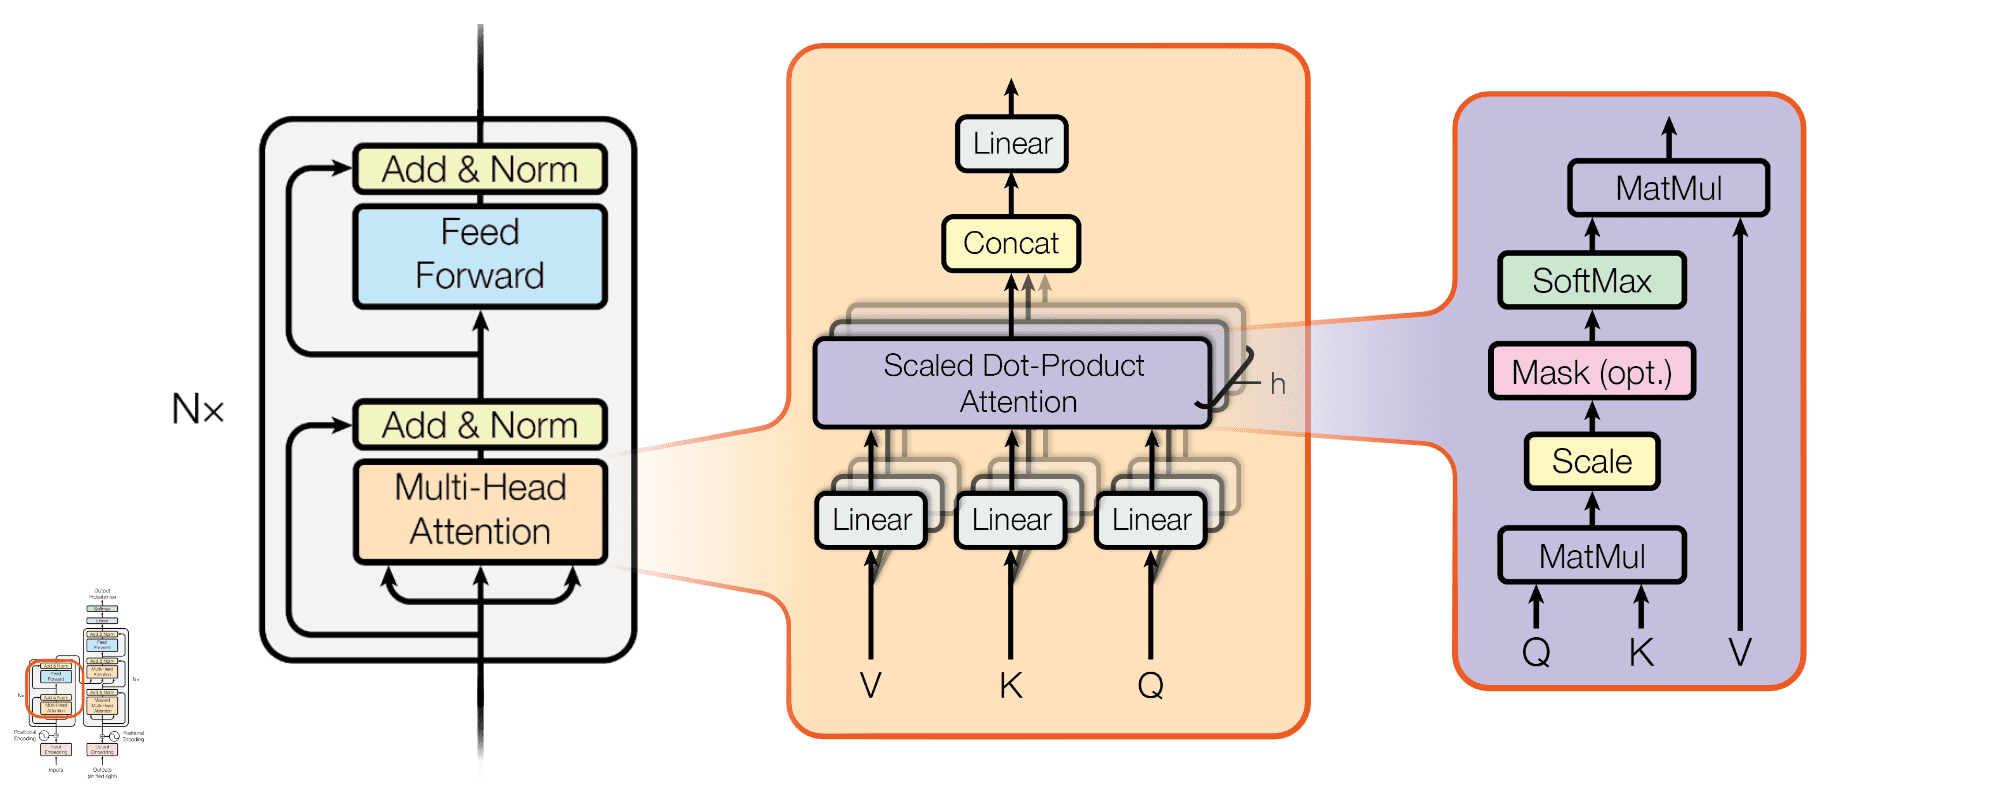
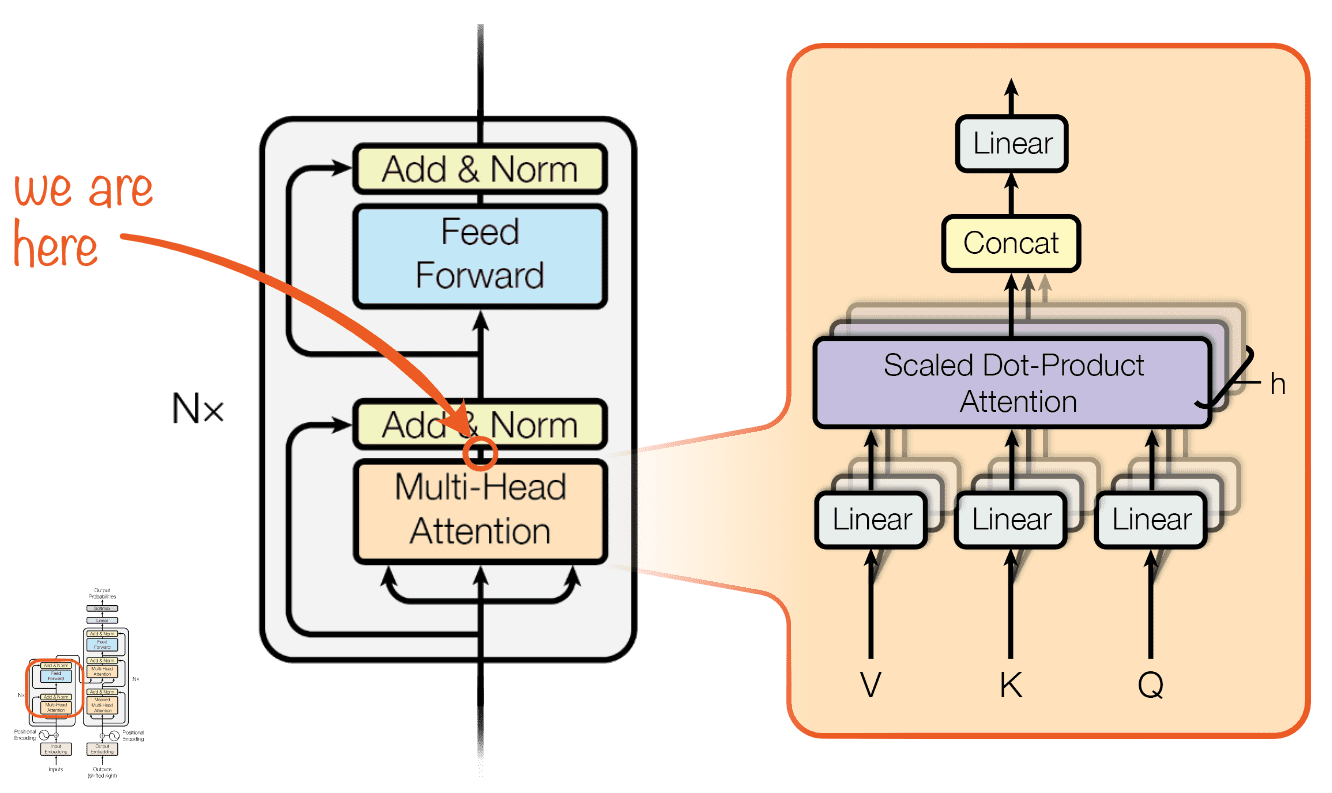
Let’s bring in two more diagrams from Figure 2 of the paper: Multi-Head Attention and Scaled Dot-Product Attention.

Transformer Multi-Head Attention

Read the V (values), K (keys), and Q (queries) labels in the middle and right sub-figures as names rather than objects. In code, they’d be function parameter names. They might or might not correspond to the same value. In the case of the encoder, all three inputs of the middle sub-figure carry the same matrix: z(ℓ−1)\mathbf{z}^{(\ell-1)}! This is the trident we saw earlier—binding the input to parameter names.

You can see that each of the V, K, Q lines on the diagram forks further into hh separate branches, the heads, matching its Multi-Head name. Think of each head as an independent computation process. Each has the same structure and its own parameters, so each can focus on different features of the input.

In the paper, the authors use h=8h = 8 heads. So the layer input z(ℓ−1)\mathbf{z}^{(\ell-1)} inside Multi-Head Attention is really referenced 3×8=243 \times 8 = 24 times: V, K, Q once for each head.

Inside an Encoder Attention Head

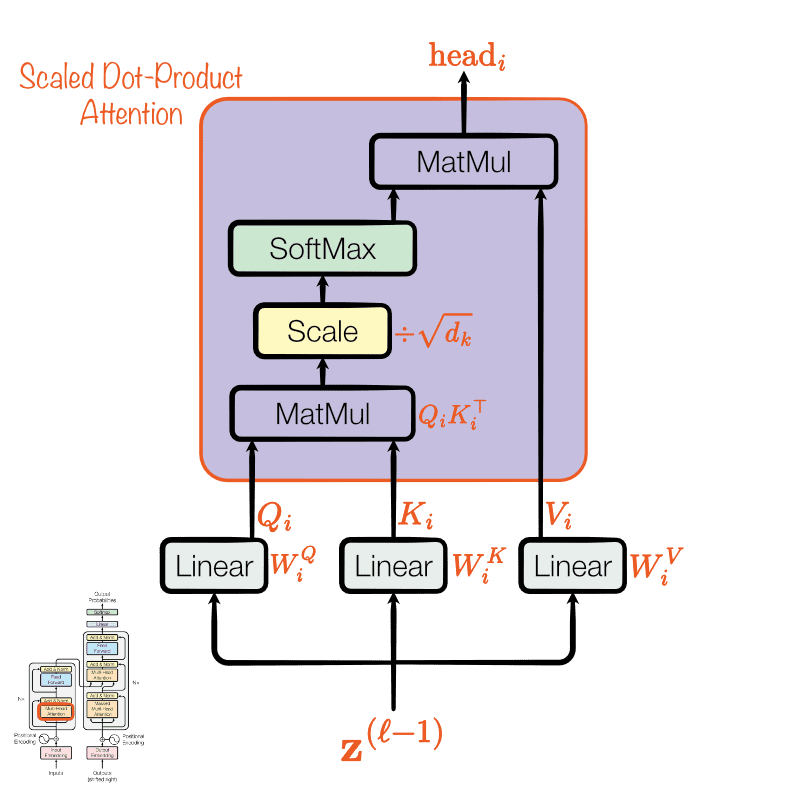
Let’s bring our attention (pun!) to a single attention head. I’ll zoom in on the diagram and make it more concrete. For this one, I dropped the paper’s Mask (opt.) box between Scale and SoftMax because only the decoder uses it; we’ll get to it there.

Attention Head

Let’s follow the numbers first by looking at the queries Qi=z(ℓ−1)WiQQ_i = \mathbf{z}^{(\ell-1)} W^Q_i.

We haven’t seen WiQW^Q_i before. It is a matrix of learned parameters. Each row of z(ℓ−1)\mathbf{z}^{(\ell-1)} carries information about one token. Multiplying the two projects the input sequence into a list of questions. Keep this abstract for now.

Let’s look at the keys Ki=z(ℓ−1)WiKK_i = \mathbf{z}^{(\ell-1)} W^K_i.

As with the queries, we project the input sequence into a list of keys.

If you follow the row-by-column matrix multiplication, you’ll notice that there is no interaction between the elements of the input sequence! In the first layer, the only signal comes from the token itself and its position in the input sequence.

This brings us to the first operation of Scaled Dot-Product Attention: QiKi⊤Q_i K_i^\top:

Ana␣are␣mere.[  q1    q2    q3    q4    q5  ]⏟Qi ∈ R5×64k1Ank1ak1␣arek1␣merek1.[k1k2k3k4k5]⏟Ki⊤ ∈ R64×5=[q1⋅k1q1⋅k2q1⋅k3q1⋅k4q1⋅k5q2⋅k1q2⋅k2q2⋅k3q2⋅k4q2⋅k5q3⋅k1q3⋅k2q3⋅k3q3⋅k4q3⋅k5q4⋅k1q4⋅k2q4⋅k3q4⋅k4q4⋅k5q5⋅k1q5⋅k2q5⋅k3q5⋅k4q5⋅k5]⏟QiKi⊤ ∈ R5×5\def\rowvec#1{\rule[0.5ex]{1em}{0.4pt}\;#1\;\rule[0.5ex]{1em}{0.4pt}} \def\colvec#1{\hspace{0.35em}\begin{matrix}\rule{0.4pt}{1.3em}\\[-0.3em] #1 \\[-0.3em] \rule{0.4pt}{1.3em}\end{matrix}\hspace{0.35em}} \def\klabel#1{\hspace{0.35em}\overset{\mathclap{#1}}{\phantom{k_1}}\hspace{0.35em}} \def\qc#1{\textcolor{d6336c}{#1}} \def\kc#1{\textcolor{00897b}{#1}} \begin{gathered} \begin{array}{r} \scriptstyle\texttt{An} \\ \scriptstyle\texttt{a} \\ \qc{\scriptstyle\texttt{\char"2423{}are}} \\ \scriptstyle\texttt{\char"2423{}mere} \\ \scriptstyle\texttt{.} \end{array} \underbrace{\begin{bmatrix} \rowvec{q_1} \\ \rowvec{q_2} \\ \qc{\rowvec{q_3}} \\ \rowvec{q_4} \\ \rowvec{q_5} \end{bmatrix}}_{Q_i \,\in\, \mathbb{R}^{5 \times 64}} \underbrace{\begin{array}{c} \begin{matrix} \klabel{\scriptstyle\texttt{An}} & \klabel{\scriptstyle\texttt{a}} & \klabel{\scriptstyle\texttt{\char"2423{}are}} & \klabel{\kc{\scriptstyle\texttt{\char"2423{}mere}}} & \klabel{\scriptstyle\texttt{.}} \end{matrix} \\[-0.4em] \begin{bmatrix} \colvec{k_1} & \colvec{k_2} & \colvec{k_3} & \kc{\colvec{k_4}} & \colvec{k_5} \end{bmatrix} \end{array}}_{K_i^\top \,\in\, \mathbb{R}^{64 \times 5}} \\[1em] = \underbrace{\begin{bmatrix} q_1 \cdot k_1 & q_1 \cdot k_2 & q_1 \cdot k_3 & q_1 \cdot \kc{k_4} & q_1 \cdot k_5 \\ q_2 \cdot k_1 & q_2 \cdot k_2 & q_2 \cdot k_3 & q_2 \cdot \kc{k_4} & q_2 \cdot k_5 \\ \qc{q_3} \cdot k_1 & \qc{q_3} \cdot k_2 & \qc{q_3} \cdot k_3 & \qc{q_3} \cdot \kc{k_4} & \qc{q_3} \cdot k_5 \\ q_4 \cdot k_1 & q_4 \cdot k_2 & q_4 \cdot k_3 & q_4 \cdot \kc{k_4} & q_4 \cdot k_5 \\ q_5 \cdot k_1 & q_5 \cdot k_2 & q_5 \cdot k_3 & q_5 \cdot \kc{k_4} & q_5 \cdot k_5 \end{bmatrix}}_{Q_i K_i^\top \,\in\, \mathbb{R}^{5 \times 5}} \end{gathered}

The result is a 5×55 \times 5 matrix of attention scores: row tt says how much attention position tt pays to every position in the input sequence, itself included. Every entry is a dot product, which measures how well a query and a key line up.

Each score adds up 64 products (the size of each query and key, dk=dmodel/h=512/8d_k = d_\text{model} / h = 512 / 8), so the scores get large. Scale divides them by dk=8\sqrt{d_k} = 8, and SoftMax makes them relative by turning each row into a split of attention that sums to 1:

softmax(x)s=exs∑rexr\text{softmax}(x)_s = \frac{e^{x_s}}{\sum_r e^{x_r}}

For the ␣are row, with made-up scores:

Ana␣are␣mere.
raw score3−6922−4
÷ 80.375−0.751.1252.75−0.5
SoftMax0.0680.0220.1450.7360.029

␣are puts 74% of its attention on ␣mere and 14% on itself. Without Scale, ␣mere would take 99.9998%. The authors suspect such extremes make training hard (Section 3.2.1).

The result is a 5×55 \times 5 matrix of attention weights, one row per token:

softmax ⁣(QiKi⊤dk)\text{softmax}\!\left(\frac{Q_i K_i^\top}{\sqrt{d_k}}\right)

Let’s look at the values Vi=z(ℓ−1)WiVV_i = \mathbf{z}^{(\ell-1)} W^V_i.

As with the queries and keys, we project the input sequence, this time into a list of values: the information each token passes on when another token attends to it.

Remember the trident? Queries, keys, and values all come from the same z(ℓ−1)\mathbf{z}^{(\ell-1)}: the sentence is attending to itself. That’s the self in self-attention.

Now that we’ve figured out the attention between the tokens, let’s make the information actually flow. So far, nothing has moved: the weights only say who listens to whom. The last MatMul does the moving. Let’s call the weights α\alpha:

α=softmax ⁣(QiKi⊤dk),headi=α Vi\alpha = \text{softmax}\!\left(\frac{Q_i K_i^\top}{\sqrt{d_k}}\right), \qquad \text{head}_i = \alpha\, V_iAna␣are␣mere.[  α1    α2    α3    α4    α5  ]⏟α ∈ R5×5 [  v1    v2    v3    v4    v5  ]⏟Vi ∈ R5×64=[  α1Vi    α2Vi    α3Vi    α4Vi    α5Vi  ]⏟headi ∈ R5×64\def\shortrow#1{\rule[0.5ex]{0.5em}{0.4pt}\;#1\;\rule[0.5ex]{0.5em}{0.4pt}} \def\longrow#1{\rule[0.5ex]{1.4em}{0.4pt}\;#1\;\rule[0.5ex]{1.4em}{0.4pt}} \def\qc#1{\textcolor{d6336c}{#1}} \def\kc#1{\textcolor{00897b}{#1}} \begin{array}{r} \scriptstyle\texttt{An} \\ \scriptstyle\texttt{a} \\ \qc{\scriptstyle\texttt{\char"2423{}are}} \\ \scriptstyle\texttt{\char"2423{}mere} \\ \scriptstyle\texttt{.} \end{array} \underbrace{\begin{bmatrix} \shortrow{\alpha_1} \\ \shortrow{\alpha_2} \\ \qc{\shortrow{\alpha_3}} \\ \shortrow{\alpha_4} \\ \shortrow{\alpha_5} \end{bmatrix}}_{\alpha \,\in\, \mathbb{R}^{5 \times 5}} \, \underbrace{\begin{bmatrix} \longrow{v_1} \\ \longrow{v_2} \\ \longrow{v_3} \\ \kc{\longrow{v_4}} \\ \longrow{v_5} \end{bmatrix}}_{V_i \,\in\, \mathbb{R}^{5 \times 64}} = \underbrace{\begin{bmatrix} \longrow{\alpha_1 V_i} \\ \longrow{\alpha_2 V_i} \\ \qc{\longrow{\alpha_3 V_i}} \\ \longrow{\alpha_4 V_i} \\ \longrow{\alpha_5 V_i} \end{bmatrix}}_{\text{head}_i \,\in\, \mathbb{R}^{5 \times 64}}

Each row of α\alpha is one token’s split of attention, and each row of ViV_i is one token’s value. Multiply them, and row tt of headi\text{head}_i becomes a blend of all the values, mixed in the proportions of αt\alpha_t. Here’s the blend for ␣are, with the weights from the table above:

α3Vi␣are=0.068 v1An+0.022 v2a+0.145 v3␣are+0.736 v4␣mere+0.029 v5.\def\qc#1{\textcolor{d6336c}{#1}} \def\kc#1{\textcolor{00897b}{#1}} \underset{\mathclap{\qc{\texttt{\char"2423{}are}}}}{\qc{\alpha_3 V_i}} = 0.068\, \underset{\mathclap{\texttt{An}}}{v_1} + 0.022\, \underset{\mathclap{\texttt{a}}}{v_2} + 0.145\, \underset{\mathclap{\texttt{\char"2423{}are}}}{v_3} + \kc{0.736\, \underset{\mathclap{\texttt{\char"2423{}mere}}}{v_4}} + 0.029\, \underset{\mathclap{\texttt{.}}}{v_5}

␣are comes out 74% ␣mere’s value, 14% its own, and the rest from the other tokens. Every row gets its own blend.

Before this MatMul, each row of ViV_i came from one row of the input. Now each row of headi\text{head}_i carries something from the whole sentence.

In the first layer, an input row knows only its own token and position. From the second layer on, it already carries context from the layer below, so each layer builds on the ones before.

That’s one head. The other seven do the same with their own weights, and each produces its own 5×645 \times 64 headi\text{head}_i.

Putting the Heads Together

Back to the Multi-Head Attention diagram. Two boxes are left above the heads, Concat and Linear. Together they compute:

MultiHead(Q,K,V)=Concat(head1,…,headh) WO\text{MultiHead}(Q, K, V) = \text{Concat}(\text{head}_1, \ldots, \text{head}_h)\, W^O

Concat puts the eight heads side by side. Each token’s row grows from 64 to 8×64=5128 \times 64 = 512 numbers, back to dmodeld_\text{model}:

Ana␣are␣mere.[Ana␣are␣mere.head1head2head3head4head5head6head7head8]⏟Concat(head1,…,head8) ∈ R5×512\def\hcol#1#2{\textcolor{#1}{\begin{matrix} \rule{1.35em}{2.2em} \\[-0.25em] \scriptstyle\text{head}_{\mathrlap{#2}} \\[-0.25em] \rule{1.35em}{2.2em} \end{matrix}}} \def\hg{\hspace{0.51em}} \def\tok{\begin{array}{r} \scriptstyle\texttt{An} \\ \scriptstyle\texttt{a} \\ \scriptstyle\texttt{\char"2423{}are} \\ \scriptstyle\texttt{\char"2423{}mere} \\ \scriptstyle\texttt{.} \end{array}} \tok \underbrace{\begin{bmatrix} \vphantom{\tok} \hcol{2a78d6}{1}\hg\hcol{d95926}{2}\hg\hcol{199e70}{3}\hg\hcol{bd7f00}{4}\hg \hcol{d55181}{5}\hg\hcol{008300}{6}\hg\hcol{7a6be0}{7}\hg\hcol{e34948}{8}\hspace{0.2em} \end{bmatrix}}_{\text{Concat}(\text{head}_1, \ldots, \text{head}_8) \,\in\, \mathbb{R}^{5 \times 512}}

Each color is one head’s 64 columns. Row ␣are now holds eight blends of the sentence, one from each head. The heads haven’t seen each other’s results yet.

Linear multiplies by one more matrix of learned parameters, WO∈R512×512W^O \in \mathbb{R}^{512 \times 512}:

Ana␣are␣mere.[Ana␣are␣mere.head1head2head3head4head5head6head7head8]⏟Concat(head1,…,head8) ∈ R5×512↓  ×WOAna␣are␣mere.[]⏟MultiHead ∈ R5×512\def\hcol#1#2{\textcolor{#1}{\begin{matrix} \rule{1.35em}{2.2em} \\[-0.25em] \scriptstyle\text{head}_{\mathrlap{#2}} \\[-0.25em] \rule{1.35em}{2.2em} \end{matrix}}} \def\hg{\hspace{0.51em}} \def\mb#1{\textcolor{#1}{\rule[-0.1em]{0.4506em}{0.7em}}\hspace{0.05em}} \def\mrowa{\mb{008300}\mb{d95926}\mb{d55181}\mb{7a6be0}\mb{2a78d6}\mb{d95926}\mb{e34948}\mb{d55181} \mb{2a78d6}\mb{bd7f00}\mb{008300}\mb{2a78d6}\mb{008300}\mb{d95926}\mb{2a78d6}\mb{d95926} \mb{d55181}\mb{bd7f00}\mb{2a78d6}\mb{199e70}\mb{2a78d6}\mb{008300}\mb{bd7f00}\mb{2a78d6} \mb{e34948}\mb{d55181}\mb{2a78d6}\mb{199e70}\mb{7a6be0}\mb{008300}\mb{d55181}\mb{2a78d6}} \def\mrowb{\mb{7a6be0}\mb{2a78d6}\mb{199e70}\mb{2a78d6}\mb{008300}\mb{e34948}\mb{d95926}\mb{bd7f00} \mb{d55181}\mb{d95926}\mb{008300}\mb{2a78d6}\mb{008300}\mb{199e70}\mb{008300}\mb{e34948} \mb{008300}\mb{d95926}\mb{2a78d6}\mb{008300}\mb{d55181}\mb{7a6be0}\mb{d95926}\mb{bd7f00} \mb{2a78d6}\mb{008300}\mb{7a6be0}\mb{2a78d6}\mb{008300}\mb{2a78d6}\mb{008300}\mb{d95926}} \def\mrowc{\mb{e34948}\mb{008300}\mb{d55181}\mb{bd7f00}\mb{e34948}\mb{199e70}\mb{d55181}\mb{008300} \mb{bd7f00}\mb{199e70}\mb{bd7f00}\mb{d95926}\mb{e34948}\mb{d95926}\mb{7a6be0}\mb{e34948} \mb{d95926}\mb{2a78d6}\mb{008300}\mb{199e70}\mb{008300}\mb{bd7f00}\mb{199e70}\mb{7a6be0} \mb{bd7f00}\mb{199e70}\mb{008300}\mb{2a78d6}\mb{d95926}\mb{008300}\mb{bd7f00}\mb{d95926}} \def\mrowd{\mb{008300}\mb{d95926}\mb{d55181}\mb{bd7f00}\mb{2a78d6}\mb{7a6be0}\mb{2a78d6}\mb{e34948} \mb{d55181}\mb{008300}\mb{e34948}\mb{7a6be0}\mb{199e70}\mb{bd7f00}\mb{7a6be0}\mb{199e70} \mb{008300}\mb{bd7f00}\mb{008300}\mb{e34948}\mb{bd7f00}\mb{2a78d6}\mb{e34948}\mb{2a78d6} \mb{bd7f00}\mb{d55181}\mb{7a6be0}\mb{008300}\mb{2a78d6}\mb{d95926}\mb{7a6be0}\mb{008300}} \def\mrowe{\mb{d55181}\mb{7a6be0}\mb{d55181}\mb{7a6be0}\mb{e34948}\mb{bd7f00}\mb{199e70}\mb{7a6be0} \mb{bd7f00}\mb{7a6be0}\mb{199e70}\mb{2a78d6}\mb{d55181}\mb{199e70}\mb{d95926}\mb{008300} \mb{2a78d6}\mb{d55181}\mb{2a78d6}\mb{199e70}\mb{e34948}\mb{199e70}\mb{d95926}\mb{7a6be0} \mb{d95926}\mb{d55181}\mb{bd7f00}\mb{e34948}\mb{bd7f00}\mb{2a78d6}\mb{199e70}\mb{d55181}} \def\tok{\begin{array}{r} \scriptstyle\texttt{An} \\ \scriptstyle\texttt{a} \\ \scriptstyle\texttt{\char"2423{}are} \\ \scriptstyle\texttt{\char"2423{}mere} \\ \scriptstyle\texttt{.} \end{array}} \begin{gathered} \tok \underbrace{\begin{bmatrix} \vphantom{\tok} \hcol{2a78d6}{1}\hg\hcol{d95926}{2}\hg\hcol{199e70}{3}\hg\hcol{bd7f00}{4}\hg \hcol{d55181}{5}\hg\hcol{008300}{6}\hg\hcol{7a6be0}{7}\hg\hcol{e34948}{8}\hspace{0.2em} \end{bmatrix}}_{\text{Concat}(\text{head}_1, \ldots, \text{head}_8) \,\in\, \mathbb{R}^{5 \times 512}} \\[0.6em] \Big\downarrow \mathrlap{\; \times W^O} \\[0.6em] \tok \underbrace{\begin{bmatrix} \mrowa \\ \mrowb \\ \mrowc \\ \mrowd \\ \mrowe \end{bmatrix}}_{\text{MultiHead} \,\in\, \mathbb{R}^{5 \times 512}} \end{gathered}

Each output number is a row of Concat times a column of WOW^O, so it mixes all eight heads. Attention mixed information across tokens, the rows. Linear mixes across heads.

Encoder Multi-Head

Residual Connection

Next on the diagram is the Add & Norm box.

Encoder Residual

Look closely at the arrows. The layer input z(ℓ−1)\mathbf{z}^{(\ell-1)} goes through Multi-Head Attention, and it also goes around it, unchanged, straight into Add & Norm. That bypass is the residual connection.

The Add is plain addition:

z(ℓ−1)⏟5×512+MultiHead(z(ℓ−1),z(ℓ−1),z(ℓ−1))⏟5×512∈R5×512\def\addnorm#1{\textcolor{b8860b}{#1}} \def\attn#1{\textcolor{e0701a}{#1}} \underbrace{\mathbf{z}^{(\ell-1)}}_{5 \times 512} \mathbin{\addnorm{+}} \underbrace{\attn{\text{MultiHead}}(\mathbf{z}^{(\ell-1)}, \mathbf{z}^{(\ell-1)}, \mathbf{z}^{(\ell-1)})}_{5 \times 512} \in \mathbb{R}^{5 \times 512}

Think of attention’s output as a diff we apply to the input. Each token keeps what it already had and picks up context from the other tokens. The idea comes from ResNet4 (2015), an image recognition model. It’s called residual because the sub-layer only computes the difference, what to add to its input.

The Norm is layer normalization5. Layer after layer, we keep adding to each token’s vector. LayerNorm shifts and rescales its 512 numbers to average 0 with a typical size of 1, so they don’t grow out of hand. We’ll name the result a\mathbf{a}:

a=LayerNorm1(z(ℓ−1)+MultiHead(z(ℓ−1),z(ℓ−1),z(ℓ−1)))\def\addnorm#1{\textcolor{b8860b}{#1}} \def\attn#1{\textcolor{e0701a}{#1}} \mathbf{a} = \addnorm{\text{LayerNorm}_1}\big(\mathbf{z}^{(\ell-1)} \mathbin{\addnorm{+}} \attn{\text{MultiHead}}(\mathbf{z}^{(\ell-1)}, \mathbf{z}^{(\ell-1)}, \mathbf{z}^{(\ell-1)})\big)

Encoder Feed-Forward Network

So far, we’ve mostly mixed information between tokens with fairly simple linear projections (all those Linear boxes we saw). The Feed Forward box takes it to the next level: this is where much of the interesting computation happens.

The feed-forward network is one of the oldest building blocks of machine learning: a multilayer perceptron6 (MLP) with one hidden layer (Section 3.3).

One interesting detail about this computation: it runs on each token independently. I’ll hand-wave here and say that we’re computing something about each token.

FFN(x)=max⁡(0, xW1⏟512×2048+b1)⏞ReLUW2⏟2048×512+b2\def\ffn#1{\textcolor{2b8cc4}{#1}} \ffn{\text{FFN}}(x) = \overbrace{\max(0,\ x \underbrace{W_1}_{\mathclap{512 \times 2048}} + b_1)}^{\text{ReLU}} \underbrace{W_2}_{\mathclap{2048 \times 512}} + b_2Anz1(0)az1(0)␣arez1(0)␣merez1(0).z1(0)[a1z1(0)a2z1(0)a3z1(0)a4z1(0)a5z1(0)]⏟a ∈ R5×512[W1]⏟512×2048+ b1=[0.4−0.71.5⋯−0.2−0.90.30.6⋯0.50.8−1.30.2⋯1.11.20.1−0.4⋯−1.6−0.30.9−1.1⋯0.7]⏟5×2048\def\rowvec#1{\mathrlap{\rule[0.5ex]{1em}{0.4pt}}\hspace{0.28em} & #1\vphantom{z^{(0)}_1} & \hspace{0.28em}\mathllap{\rule[0.5ex]{1em}{0.4pt}}} \begin{array}{r} {\scriptstyle\texttt{An}}\vphantom{z^{(0)}_1} \\ {\scriptstyle\texttt{a}}\vphantom{z^{(0)}_1} \\ {\scriptstyle\texttt{\char"2423{}are}}\vphantom{z^{(0)}_1} \\ {\scriptstyle\texttt{\char"2423{}mere}}\vphantom{z^{(0)}_1} \\ {\scriptstyle\texttt{.}}\vphantom{z^{(0)}_1} \end{array} \underbrace{\begin{bmatrix} \rowvec{a_1} \\ \rowvec{a_2} \\ \rowvec{a_3} \\ \rowvec{a_4} \\ \rowvec{a_5} \end{bmatrix}}_{\mathbf{a} \,\in\, \mathbb{R}^{5 \times 512}} \underbrace{\begin{bmatrix} \rule[-0.5em]{0pt}{1.5em}\hspace{1.9em} W_1 \hspace{1.9em} \end{bmatrix}}_{512 \times 2048} +\, b_1 = \underbrace{\begin{bmatrix*}[r] 0.4 & -0.7 & 1.5 & \cdots & -0.2 \\ -0.9 & 0.3 & 0.6 & \cdots & 0.5 \\ 0.8 & -1.3 & 0.2 & \cdots & 1.1 \\ 1.2 & 0.1 & -0.4 & \cdots & -1.6 \\ -0.3 & 0.9 & -1.1 & \cdots & 0.7 \end{bmatrix*}}_{5 \times 2048}→ ReLU [0.401.5⋯000.30.6⋯0.50.800.2⋯1.11.20.10⋯000.90⋯0.7][W2]⏟2048×512+ b2\def\ffn#1{\textcolor{2b8cc4}{#1}} \xrightarrow{\ \text{ReLU}\ } \begin{bmatrix*}[r] 0.4 & \ffn{0} & 1.5 & \cdots & \ffn{0} \\ \ffn{0} & 0.3 & 0.6 & \cdots & 0.5 \\ 0.8 & \ffn{0} & 0.2 & \cdots & 1.1 \\ 1.2 & 0.1 & \ffn{0} & \cdots & \ffn{0} \\ \ffn{0} & 0.9 & \ffn{0} & \cdots & 0.7 \end{bmatrix*} \underbrace{\begin{bmatrix} \rule[-2.2em]{0pt}{4.9em}\hspace{0.4em} W_2 \hspace{0.4em} \end{bmatrix}}_{2048 \times 512} +\, b_2=[FFN(a1)z1(0)FFN(a2)z1(0)FFN(a3)z1(0)FFN(a4)z1(0)FFN(a5)z1(0)]⏟FFN(a) ∈ R5×512\def\ffn#1{\textcolor{2b8cc4}{#1}} \def\rowvec#1{\mathrlap{\rule[0.5ex]{1em}{0.4pt}}\hspace{0.28em} & #1\vphantom{z^{(0)}_1} & \hspace{0.28em}\mathllap{\rule[0.5ex]{1em}{0.4pt}}} = \underbrace{\begin{bmatrix} \rowvec{\ffn{\text{FFN}}(a_1)} \\ \rowvec{\ffn{\text{FFN}}(a_2)} \\ \rowvec{\ffn{\text{FFN}}(a_3)} \\ \rowvec{\ffn{\text{FFN}}(a_4)} \\ \rowvec{\ffn{\text{FFN}}(a_5)} \end{bmatrix}}_{\ffn{\text{FFN}}(\mathbf{a}) \,\in\, \mathbb{R}^{5 \times 512}}

Then another Add & Norm, which we already saw:

z(ℓ)=LayerNorm2(a+FFN(a))\def\addnorm#1{\textcolor{b8860b}{#1}} \def\ffn#1{\textcolor{2b8cc4}{#1}} \mathbf{z}^{(\ell)} = \addnorm{\text{LayerNorm}_2}\big(\mathbf{a} \mathbin{\addnorm{+}} \ffn{\text{FFN}}(\mathbf{a})\big)

Six Layers Later

That’s one encoder layer. The stack repeats it N=6N = 6 times, each time with its own parameters θℓ\theta_\ell:

z(0)→ θ1 z(1)→ θ2 ⋯→ θ6 z(6)=z=(z1,…,z5)\mathbf{z}^{(0)} \xrightarrow{\ \theta_1\ } \mathbf{z}^{(1)} \xrightarrow{\ \theta_2\ } \cdots \xrightarrow{\ \theta_6\ } \mathbf{z}^{(6)} = \mathbf{z} = (z_1, \ldots, z_5)

Out of the last layer comes z\mathbf{z}, the latent representation from the overview: a list of vectors that capture the phrase’s meaning rather than its spelling.

Encoder-Only Models

This was the encoder: halfway through the Transformer, but an important milestone. Remember I mentioned encoder-only variants? If you’ve heard about classification or similarity problems, that’s pretty much what’s behind them. Their outputs are built on this meaningful representation.

Google’s BERT7 (2018) is the best-known encoder-only model. Its output is z\mathbf{z}, and we put it to work with a small extra step on top.

TODO: Explain the BERT name. Good moment to reiterate that encoder’s attention is bidirectional.

For classification, a small classifier turns z\mathbf{z} into a label: positive or negative, spam or ham, which topic.

For similarity, we pool z\mathbf{z} into one vector, for example by averaging z1,…,z5z_1, \ldots, z_5. In models built for this, phrases with similar meaning get vectors that point the same way, and cosine similarity (a dot product of the vectors scaled to length 1) tells us how well they line up, just like queries and keys, minus the length. This is what powers semantic search.

A Decoder Step

But the main reason we’re here is to turn this meaningful representation back into text, English text.

I’ll move quickly here, as I’ve already covered all the shared elements in the Through the Encoder section, which I assume you read carefully.

Let’s annotate the Transformer diagram. The decoder (right side of the diagram) takes two inputs: the encoder’s output z\mathbf{z}, which we just figured out, and BOS, the word that starts every output (see Auto-regressive Generation). Out comes P(y1∣y<1,x)P(y_1 \mid y_{<1}, \mathbf{x}), the probability distribution of the next token over the whole vocabulary, given the prefix y<1y_{<1} (just BOS) and the input x\mathbf{x} (Ana are mere.). It’s a list of 50257 probabilities, one per token ID.

From Encoder to Decoder

The decoder side is structurally very similar to the encoder. You can make this observation visually too. There are no new kinds of boxes. The only structural differences are an additional attention sub-layer in the middle of each decoder layer, and the Linear and Softmax boxes at the top that turn the last hidden representation into the probability distribution.

The bottom sub-layer uses Masked Multi-Head Attention. The mask stops each token from attending to the tokens after it. This is better known as causal attention. With BOS as our only input, there’s nothing after it to hide, so the mask plays no role yet. It starts to matter at the next step, when we append the first generated token, and during training.

Let’s run one decoder step and watch the first English token come into existence.

At this first step, the decoder’s input is the prefix y<1y_{<1}, which holds just BOS:

y<1=(⟨BOS⟩y0)y_{<1} = (\underset{y_0}{\langle\text{BOS}\rangle})

The decoder’s input starts out like the encoder’s. Output Embedding is the same matrix EE as Input Embedding (Section 3.4). A single table works for both languages because they share the vocabulary, r50k_base. BOS is <|endoftext|>, token ID 50256, so we look up its row E50256E_{50256}, add the positional encoding for position 0, PE0PE_0, and get the decoder’s first hidden state s(0)\mathbf{s}^{(0)}:

[E50256s1(0)]⏟embedding+[PE0s1(0)]⏟position=[s1(0)s1(0)]⏟s(0)∈R1×512\def\rowvec#1{\mathrlap{\rule[0.5ex]{1em}{0.4pt}}\hspace{0.28em} & #1\vphantom{s^{(0)}_1} & \hspace{0.28em}\mathllap{\rule[0.5ex]{1em}{0.4pt}}} \underbrace{\begin{bmatrix} \rowvec{E_{50256}} \end{bmatrix}}_{\text{embedding}} + \underbrace{\begin{bmatrix} \rowvec{PE_0} \end{bmatrix}}_{\text{position}} = \underbrace{\begin{bmatrix} \rowvec{s^{(0)}_1} \end{bmatrix}}_{\mathbf{s}^{(0)} \in \mathbb{R}^{1 \times 512}}

Note: as in the encoder, rows count from 1 and positions from 0, so row s1s_1 comes from y0y_0 (BOS) and predicts y1y_1.

This is the first step, so s(0)\mathbf{s}^{(0)} has a single row, for BOS, with 512 numbers. Numbers are made up.

s(0)=[0.31−0.841.07⋯s1(0)−0.22]⏞512 numbers←s1(0)⟨BOS⟩\mathbf{s}^{(0)} = \overbrace{\begin{bmatrix*}[r] 0.31 & -0.84 & 1.07 & \cdots\vphantom{s^{(0)}_1} & -0.22 \end{bmatrix*}}^{512 \text{ numbers}} \begin{array}{ll} \leftarrow s^{(0)}_1 & \langle\text{BOS}\rangle \end{array}

Each next step appends a row for the token we just picked.

This hidden state makes its way into the decoder stack, which has N=6N = 6 layers too. Every one of them also takes z\mathbf{z}, the encoder’s final output.

We’ll denote the output of each layer s(1),…,s(N)\mathbf{s}^{(1)}, \ldots, \mathbf{s}^{(N)}. As with the encoder, we write the last one without a superscript: s=s(6)\mathbf{s} = \mathbf{s}^{(6)}. At this first step, all of them are 1×5121 \times 512, like s(0)\mathbf{s}^{(0)}.

s(ℓ)=DecoderLayer(s(ℓ−1),z;ϕℓ),ℓ=1,…,N\mathbf{s}^{(\ell)} = \text{DecoderLayer}\big(\mathbf{s}^{(\ell-1)}, \mathbf{z}; \phi_\ell\big), \qquad \ell = 1, \ldots, N

Every layer runs the same computation, DecoderLayer\text{DecoderLayer}, with its own parameters ϕℓ\phi_\ell. That makes three kinds of model parameters so far: EE, the θℓ\theta_\ell, and the ϕℓ\phi_\ell.

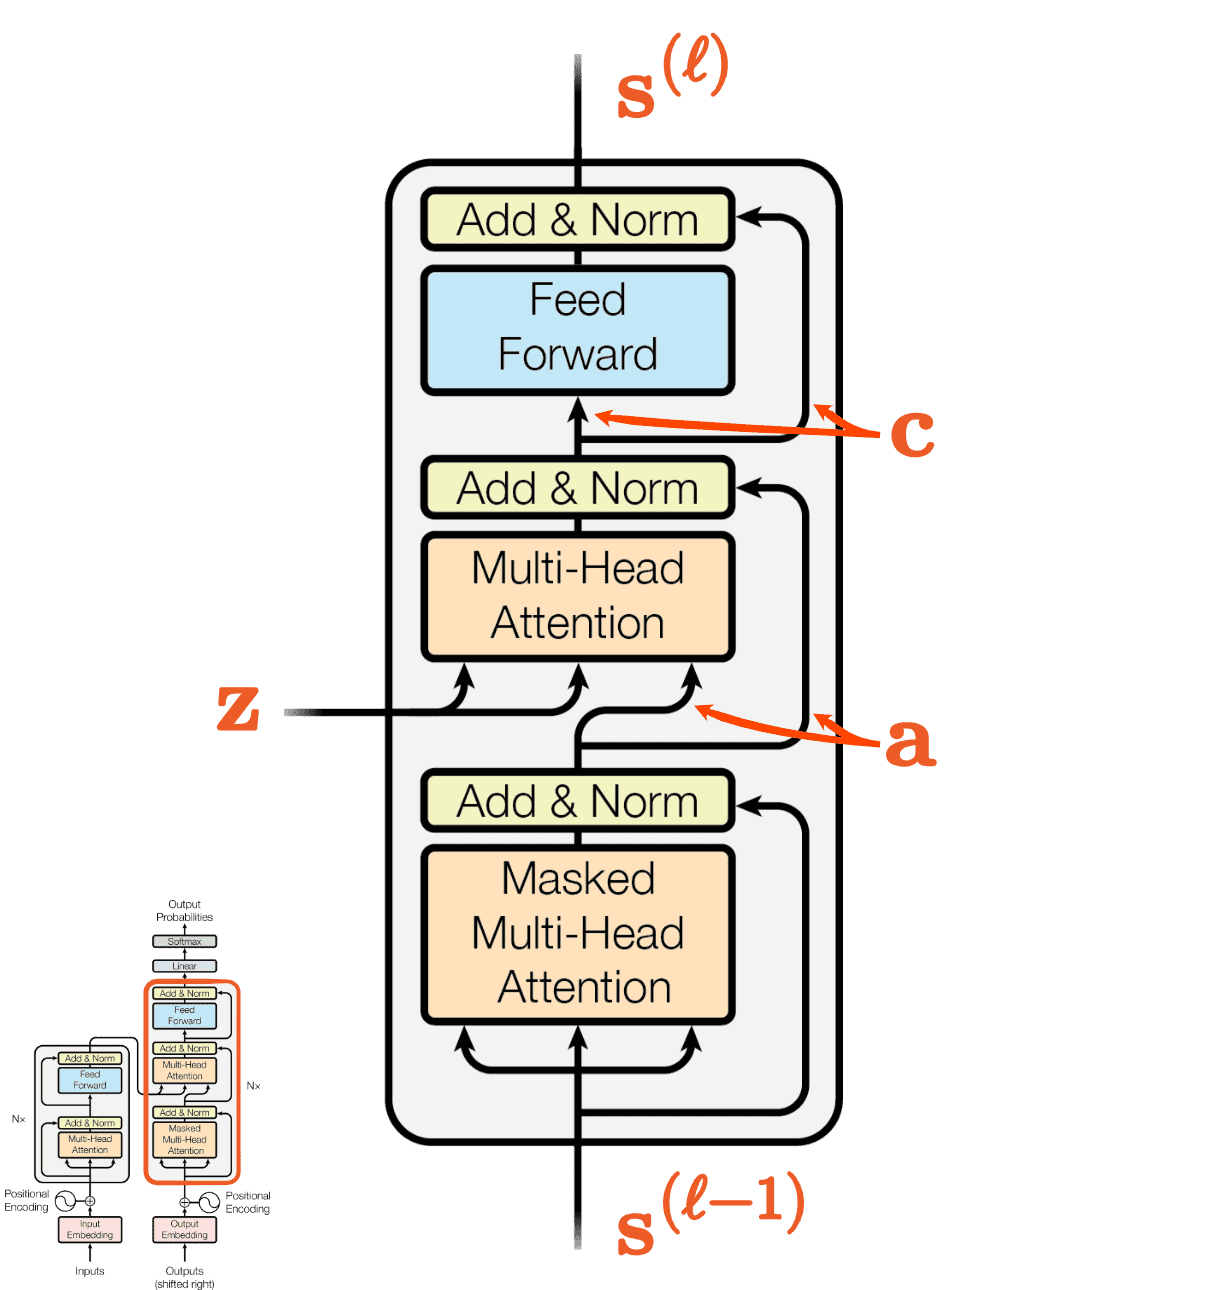
Inside a Decoder Layer

The layer input, s(ℓ−1)\mathbf{s}^{(\ell-1)}, goes through Masked Multi-Head Attention and Add & Norm. We’ll name the result a\mathbf{a}. Then a\mathbf{a} goes through the middle Multi-Head Attention, where z\mathbf{z} comes in, and another Add & Norm. We’ll name that result c\mathbf{c}. Last, c\mathbf{c} goes through Feed Forward and a third Add & Norm.

Spelling it out:

a=LayerNorm1(s(ℓ−1)+MaskedMultiHead(s(ℓ−1),s(ℓ−1),s(ℓ−1)))c=LayerNorm2(a+MultiHead(a,z,z))s(ℓ)=LayerNorm3(c+FFN(c))\def\addnorm#1{\textcolor{b8860b}{#1}} \def\attn#1{\textcolor{e0701a}{#1}} \def\ffn#1{\textcolor{2b8cc4}{#1}} \begin{aligned} \mathbf{a} &= \addnorm{\text{LayerNorm}_1}\big(\mathbf{s}^{(\ell-1)} \mathbin{\addnorm{+}} \attn{\text{MaskedMultiHead}}(\mathbf{s}^{(\ell-1)}, \mathbf{s}^{(\ell-1)}, \mathbf{s}^{(\ell-1)})\big) \\ \mathbf{c} &= \addnorm{\text{LayerNorm}_2}\big(\mathbf{a} \mathbin{\addnorm{+}} \attn{\text{MultiHead}}(\mathbf{a}, \mathbf{z}, \mathbf{z})\big) \\ \mathbf{s}^{(\ell)} &= \addnorm{\text{LayerNorm}_3}\big(\mathbf{c} \mathbin{\addnorm{+}} \ffn{\text{FFN}}(\mathbf{c})\big) \end{aligned}

In the middle line, the English tokens (a\mathbf{a}) ask the questions and the Romanian phrase (z\mathbf{z}) answers them. That’s cross-attention. The paper calls it encoder-decoder attention (Section 3.2.3):

… the memory keys and values come from the output of the encoder.

Decoder layer

Inside a Decoder Attention Head

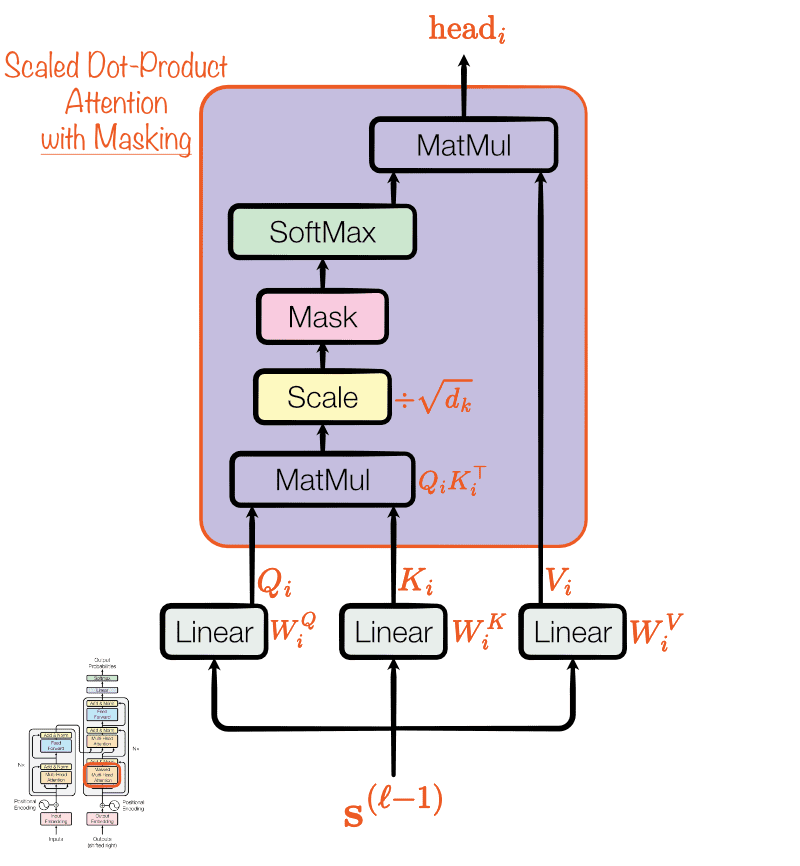
Masked Self-Attention Head

The decoder’s heads run the same math as the encoder’s, so we won’t go through all of it again. We’ll highlight the two new mechanisms, masking and cross-attention. For the rest of the math, follow Inside an Encoder Attention Head.

The head in the bottom sub-layer adds the Mask box. With only BOS, there isn’t much to look at:

⟨BOS⟩[  q1  ]⏟Qi ∈ R1×64k1⟨BOS⟩[k1]⏟Ki⊤ ∈ R64×1=[q1⋅k1]⏟QiKi⊤ ∈ R1×1\def\rowvec#1{\rule[0.5ex]{1em}{0.4pt}\;#1\;\rule[0.5ex]{1em}{0.4pt}} \def\colvec#1{\hspace{0.35em}\begin{matrix}\rule{0.4pt}{1.3em}\\[-0.3em] #1 \\[-0.3em] \rule{0.4pt}{1.3em}\end{matrix}\hspace{0.35em}} \def\klabel#1{\hspace{0.35em}\overset{\mathclap{#1}}{\phantom{k_1}}\hspace{0.35em}} \def\qc#1{\textcolor{d6336c}{#1}} \def\kc#1{\textcolor{00897b}{#1}} \begin{array}{r} \qc{\scriptstyle\langle\text{BOS}\rangle} \end{array} \underbrace{\begin{bmatrix} \qc{\rowvec{q_1}} \end{bmatrix}}_{Q_i \,\in\, \mathbb{R}^{1 \times 64}} \underbrace{\begin{array}{c} \begin{matrix} \klabel{\kc{\scriptstyle\langle\text{BOS}\rangle}} \end{matrix} \\[-0.4em] \begin{bmatrix} \kc{\colvec{k_1}} \end{bmatrix} \end{array}}_{K_i^\top \,\in\, \mathbb{R}^{64 \times 1}} = \underbrace{\begin{bmatrix} \qc{q_1} \cdot \kc{k_1} \end{bmatrix}}_{Q_i K_i^\top \,\in\, \mathbb{R}^{1 \times 1}}

BOS attends only to itself, and SoftMax turns its lone score into a weight of 1.

The mask matters once there are more tokens. Let’s skip ahead to the step where the decoder has generated An, a, ␣has, and ␣apples. Its input has five rows now, so QiKi⊤Q_i K_i^\top is 5×55 \times 5, like the encoder’s. Mask cancels attention to future tokens by adding a matrix MM to the scores:

α=softmax ⁣(QiKi⊤dk+M)\alpha = \text{softmax}\!\left(\frac{Q_i K_i^\top}{\sqrt{d_k}} + M\right)⟨BOS⟩Ana␣has␣apples⟨BOS⟩Ana␣has␣apples[0−∞−∞−∞−∞00−∞−∞−∞000−∞−∞0000−∞00000]⏟M ∈ R5×5\def\cell#1{\hspace{1.4em}\mathclap{#1}\hspace{1.4em}} \def\minf{\textcolor{d6336c}{-\infty}} \def\tok#1{\scriptstyle\texttt{#1}} \begin{array}{rc} & \begin{matrix} \cell{\scriptstyle\langle\text{BOS}\rangle} & \cell{\tok{An}} & \cell{\tok{a}} & \cell{\tok{\char"2423{}has}} & \cell{\tok{\char"2423{}apples}} \end{matrix} \\[0.2em] \begin{array}{r} \scriptstyle\langle\text{BOS}\rangle \\ \tok{An} \\ \tok{a} \\ \tok{\char"2423{}has} \\ \tok{\char"2423{}apples} \end{array} & \underbrace{\begin{bmatrix} \cell{0} & \cell{\minf} & \cell{\minf} & \cell{\minf} & \cell{\minf} \\ \cell{0} & \cell{0} & \cell{\minf} & \cell{\minf} & \cell{\minf} \\ \cell{0} & \cell{0} & \cell{0} & \cell{\minf} & \cell{\minf} \\ \cell{0} & \cell{0} & \cell{0} & \cell{0} & \cell{\minf} \\ \cell{0} & \cell{0} & \cell{0} & \cell{0} & \cell{0} \end{bmatrix}}_{M \,\in\, \mathbb{R}^{5 \times 5}} \end{array}

Each token keeps its scores for itself and the tokens before it. Every token after it gets −∞-\infty, and SoftMax turns that into a weight of 0, since e−∞=0e^{-\infty} = 0. Every token sees only what came before it, just as during generation, when the later tokens don’t exist yet.

The middle sub-layer runs the same head, with its own parameters. This time, the queries come from a\mathbf{a} (decoder hidden state) and the keys from z\mathbf{z} (encoder latent representation): Qi=aWiQQ_i = \mathbf{a} W^Q_i and Ki=zWiKK_i = \mathbf{z} W^K_i. So BOS gets a score for every Romanian token:

⟨BOS⟩[  q1  ]⏟Qi ∈ R1×64k1Ank1ak1␣arek1␣merek1.[k1k2k3k4k5]⏟Ki⊤ ∈ R64×5=[q1⋅k1q1⋅k2q1⋅k3q1⋅k4q1⋅k5]⏟QiKi⊤ ∈ R1×5\def\rowvec#1{\rule[0.5ex]{1em}{0.4pt}\;#1\;\rule[0.5ex]{1em}{0.4pt}} \def\colvec#1{\hspace{0.35em}\begin{matrix}\rule{0.4pt}{1.3em}\\[-0.3em] #1 \\[-0.3em] \rule{0.4pt}{1.3em}\end{matrix}\hspace{0.35em}} \def\klabel#1{\hspace{0.35em}\overset{\mathclap{#1}}{\phantom{k_1}}\hspace{0.35em}} \def\qc#1{\textcolor{d6336c}{#1}} \def\kc#1{\textcolor{00897b}{#1}} \begin{gathered} \begin{array}{r} \qc{\scriptstyle\langle\text{BOS}\rangle} \end{array} \underbrace{\begin{bmatrix} \qc{\rowvec{q_1}} \end{bmatrix}}_{Q_i \,\in\, \mathbb{R}^{1 \times 64}} \underbrace{\begin{array}{c} \begin{matrix} \klabel{\kc{\scriptstyle\texttt{An}}} & \klabel{\scriptstyle\texttt{a}} & \klabel{\scriptstyle\texttt{\char"2423{}are}} & \klabel{\scriptstyle\texttt{\char"2423{}mere}} & \klabel{\scriptstyle\texttt{.}} \end{matrix} \\[-0.4em] \begin{bmatrix} \kc{\colvec{k_1}} & \colvec{k_2} & \colvec{k_3} & \colvec{k_4} & \colvec{k_5} \end{bmatrix} \end{array}}_{K_i^\top \,\in\, \mathbb{R}^{64 \times 5}} \\[1em] = \underbrace{\begin{bmatrix} \qc{q_1} \cdot \kc{k_1} & \qc{q_1} \cdot k_2 & \qc{q_1} \cdot k_3 & \qc{q_1} \cdot k_4 & \qc{q_1} \cdot k_5 \end{bmatrix}}_{Q_i K_i^\top \,\in\, \mathbb{R}^{1 \times 5}} \end{gathered}

The middle sub-layer does not have the Mask box, so every English token sees the whole Romanian phrase. The English translation starts with An, like the Romanian phrase, so we’d expect BOS to give its highest score to the highlighted key.

Six Decoder Layers Later

After six decoder layers, we have s=s(6)\mathbf{s} = \mathbf{s}^{(6)}. We need one last step: turn it into a probability distribution and pick our token.

Linear projects s\mathbf{s} onto the vocabulary. Its matrix is our embedding matrix EE again, transposed (Section 3.4). Each of the 50257 scores is the dot product of s1s_1 with one token’s embedding, so a token scores high when its embedding lines up with s1s_1:

⟨BOS⟩[  s1  ]⏟s ∈ R1×512E0!⋯E2025An⋯E50256⟨EOS⟩[E0⋯E2025⋯E50256]⏟E⊤ ∈ R512×50257=[s1⋅E0⋯s1⋅E2025⋯s1⋅E50256]⏟sE⊤ ∈ R1×50257\def\rowvec#1{\rule[0.5ex]{1em}{0.4pt}\;#1\;\rule[0.5ex]{1em}{0.4pt}} \def\colvec#1{\hspace{0.35em}\begin{matrix}\rule{0.4pt}{1.3em}\\[-0.3em] #1 \\[-0.3em] \rule{0.4pt}{1.3em}\end{matrix}\hspace{0.35em}} \def\elabel#1#2{\hspace{0.35em}\overset{\mathclap{#1}}{\hphantom{#2}}\hspace{0.35em}} \def\qc#1{\textcolor{d6336c}{#1}} \def\kc#1{\textcolor{00897b}{#1}} \begin{gathered} \begin{array}{r} \qc{\scriptstyle\langle\text{BOS}\rangle} \end{array} \underbrace{\begin{bmatrix} \qc{\rowvec{s_1}} \end{bmatrix}}_{\mathbf{s} \,\in\, \mathbb{R}^{1 \times 512}} \underbrace{\begin{array}{c} \begin{matrix} \elabel{\scriptstyle\texttt{!}}{E_0} & \phantom{\cdots} & \elabel{\kc{\scriptstyle\texttt{An}}}{E_{2025}} & \phantom{\cdots} & \elabel{\scriptstyle\langle\text{EOS}\rangle}{E_{50256}} \end{matrix} \\[0em] \begin{bmatrix} \colvec{E_0} & \cdots & \kc{\colvec{E_{2025}}} & \cdots & \colvec{E_{50256}} \end{bmatrix} \end{array}}_{E^\top \,\in\, \mathbb{R}^{512 \times 50257}} \\[1em] = \underbrace{\begin{bmatrix} \qc{s_1} \cdot E_0 & \cdots & \qc{s_1} \cdot \kc{E_{2025}} & \cdots & \qc{s_1} \cdot E_{50256} \end{bmatrix}}_{\mathbf{s} E^\top \,\in\, \mathbb{R}^{1 \times 50257}} \end{gathered}

Softmax is the same function as in the attention head (see Inside an Encoder Attention Head). It turns the scores into probabilities that sum to 1:

P(y1∣y<1,x)=softmax(sE⊤)P(y_1 \mid y_{<1}, \mathbf{x}) = \text{softmax}(\mathbf{s} E^\top)

Now we pick a token. The simplest choice is the most likely one, called greedy decoding. The paper uses beam search with a beam size of 4: it keeps the 4 most likely partial translations at every step and picks the best one at the end (Section 6.1). For simplicity, I’ll use greedy and take the token with the highest probability.

Say token ID 2025, An, comes out on top. That’s our first English token, y1y_1. We append it to the decoder’s input:

y<2=(⟨BOS⟩y0,An⟨⟩y1)y_{<2} = (\underset{y_0}{\langle\text{BOS}\rangle}, \underset{y_1}{\texttt{An}\vphantom{\langle\rangle}})

Then we run the next step, starting again at A Decoder Step.
Work in progress.


  1. Attention Is All You Need. Ashish Vaswani et al., 2017.↩
  2. Scaling Laws for Neural Language Models. Jared Kaplan et al., 2020.↩
  3. Training Language Models to Follow Instructions with Human Feedback. Long Ouyang et al., 2022.↩
  4. Deep Residual Learning for Image Recognition. Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun, 2015.↩
  5. Layer Normalization. Jimmy Lei Ba, Jamie Ryan Kiros, and Geoffrey E. Hinton, 2016.↩
  6. Learning Representations by Back-Propagating Errors. David E. Rumelhart, Geoffrey E. Hinton, and Ronald J. Williams, 1986.↩
  7. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova, 2018.↩